Ask a Fort Wayne business owner what's stopping them from turning an AI agent loose on real work, and you rarely hear “it can't write.” You hear a version of the same worry: how do I know it won't confidently do the wrong thing? That single question is why so many local operators keep their AI stuck in “draft-only” mode — great for a first pass at an email, untrusted to actually send it, book it, refund it, or file it.
Something quietly shifted this month. Between September 19 and 24, four releases landed that, taken together, form a new component category for autonomous agents: small, fast models whose only job is to return a typed decision plus a calibrated confidence score for a proposed action. TypeSafe AI shipped Jev, a model that emits structured decisions instead of prose. Nokia's applied research team open-sourced AnyJev, a training-free layer that turns an existing open LLM into a calibrated decision model. And Contrastive-LM released CLM-8B, an open model that scores agent actions fast enough to run on every step in the loop.
This is not a model-release curiosity. It's the missing piece behind the objection every operations manager raises before letting an AI Employee act. Below, we translate what actually changed — plainly, and with the vendor claims labeled as claims — then hand you a buyer's checklist you can take into any AI vendor conversation in Northeast Indiana.
Key Takeaways
- A new component class emerged in September 2026: calibrated decision models that return a typed answer plus a confidence score for a proposed agent action, rather than free-form text.
- Three distinct products define it — TypeSafe AI's Jev (hosted), Nokia's AnyJev (a training-free open-source layer), and Contrastive-LM's CLM-8B (an open model that scores actions) — and they are not interchangeable.
- The point isn't smarter answers; it's a number attached to each action so the agent can decide whether to proceed, ask a human, or stop.
- This is the reflex layer (“System One”) that sits in front of your main reasoning model and gates what the agent is allowed to do.
- For Fort Wayne operators, the practical unlock is moving one high-consequence workflow from “propose” to “act” — with a confidence threshold you set and can audit.
- Vendor speed and cost figures are benchmark-specific and vendor-run; treat them as directional, not guarantees.
Why do Fort Wayne businesses keep AI stuck in “draft-only” mode?
The hesitation is rational, and the data backs it up. Adoption of agentic AI is broad but shallow: as CIO reports, McKinsey found roughly 39% of organizations experimenting with agents but only about 23% scaling them inside even a single business function. The gap between “we tried it” and “we let it run the process” is exactly where trust breaks down.
The underlying technical reason is calibration — the match between how sure a model sounds and how often it's right. Academic work is blunt about this. A 2025 study, Mind the Confidence Gap, documents that large language models are systematically miscalibrated, and warns that overconfidence “poses significant risks in critical decision-making applications.” We've written before that confidence is not competence: a model is often most certain precisely when it's wrong, because the training that makes it agreeable also rewards sounding sure.
For a local operator, that abstract problem becomes very concrete the moment an agent can do something. A draft that's wrong is a five-second fix. An accounts-receivable email sent to the wrong client, a refund issued that shouldn't have been, an intake misrouted to the wrong department — those cost real money and real trust. So the sensible default has been to keep the human as the gate on every single action. That's safe. It's also why the AI never actually saves the labor it promised: if a person has to check everything, you've automated the typing, not the work.
The calibrated-decision-model wave is aimed squarely at this wall. Instead of asking the big model to “be more careful,” it adds a small, separate model whose entire job is to put a trustworthy number on each proposed action — so the easy, high-confidence actions can flow through automatically and only the genuinely uncertain ones land on a human's desk.
What actually changed this month?
Three products, released within days of each other, established the category. They share an interface — return a typed decision with a probability, not a paragraph — but they solve different halves of the problem.
TypeSafe AI's Jev is the hosted, proprietary starting point. Per MarkTechPost's coverage, it's a transformer that accepts a state plus typed questions and returns decisions with probabilities that code can act on directly. It exposes three primitives: Choice (pick one of K options), Score (rate against an ordered rubric), and Noul (a single true/false probability, where 0.5 means undecided, not “medium”). TypeSafe attributes its calibration to a custom architecture and “Reinforcement Learning for Calibrated Decisions (RLCD),” though the architecture itself is undisclosed. Its headline benchmark — “193.6x faster” and “444.6x cheaper” than a GPT-5.6 general model — is, by the vendor's own admission, vendor-run, and the company concedes it “cannot prove the price is unsubsidized.” Notably, Jev is API-only; there are no downloadable weights.
Nokia's AnyJev answers a different question: what if you don't want to depend on one vendor's hosted model? AnyJev is a Python library, released under Apache-2.0, that turns any open LLM into a calibrated decision model with no training required. It works by reading the model's token probabilities and correcting two well-known distortions — prior bias (models tend to favor “Yes” over “No” regardless of input) and position bias (favoring whichever option appears in a certain slot). In Nokia's reported results on Qwen3-8B, applying AnyJev cut the “flip rate” when options were reversed from 0.230 to 0.073, lifted BANKING77 accuracy from 0.747 to 0.807, and — the number that matters most for automation — raised the share of decisions that were auto-decidable at a 5% error bar from 7.7% to roughly 52%. That last figure is the whole game: it's the difference between a human touching 92% of decisions and touching under half.
Contrastive-LM's CLM-8B tackles speed and openness. It's billed as the first open model in a new class the team calls Contrastive Language Models — models that, in their words, do “not generate text” but instead “score a set of candidate actions against the current state and return probabilities.” It pairs a frozen Qwen3-8B encoder with a small (20M-parameter, 75MB) trainable head, runs on a single GPU via vLLM, and is Apache-2.0. Its “up to 9x faster than Jev” headline comes from one specific benchmark (a T-Rex game where states repeat and caching helps): 16.5ms versus 149.8ms. On less cache-friendly tasks the gap narrows sharply — about 2.8x on WikiRacing and 1.6x on tool calling — and on raw accuracy CLM-8B trails Jev slightly (95.2% vs 99.2% on tool calling; 26/30 vs 30/30 on WikiRacing). Faster and open, with a small accuracy trade-off — a familiar engineering choice.
Here's how the three line up:
| Product | Maker | How you run it | What it adds | License / access |
|---|---|---|---|---|
| Jev | TypeSafe AI | Hosted API (no weights) | The reference implementation: typed Choice/Score/Noul decisions with calibrated confidence | Proprietary, early-access API |
| AnyJev | Nokia (applied research) | Python library over your own open LLM | Calibration without training — debiases token probabilities from any open model | Apache-2.0, on PyPI |
| CLM-8B | Contrastive-LM | Open weights on 1 GPU (vLLM) | A purpose-built scorer fast enough to gate every action in the loop | Apache-2.0 |
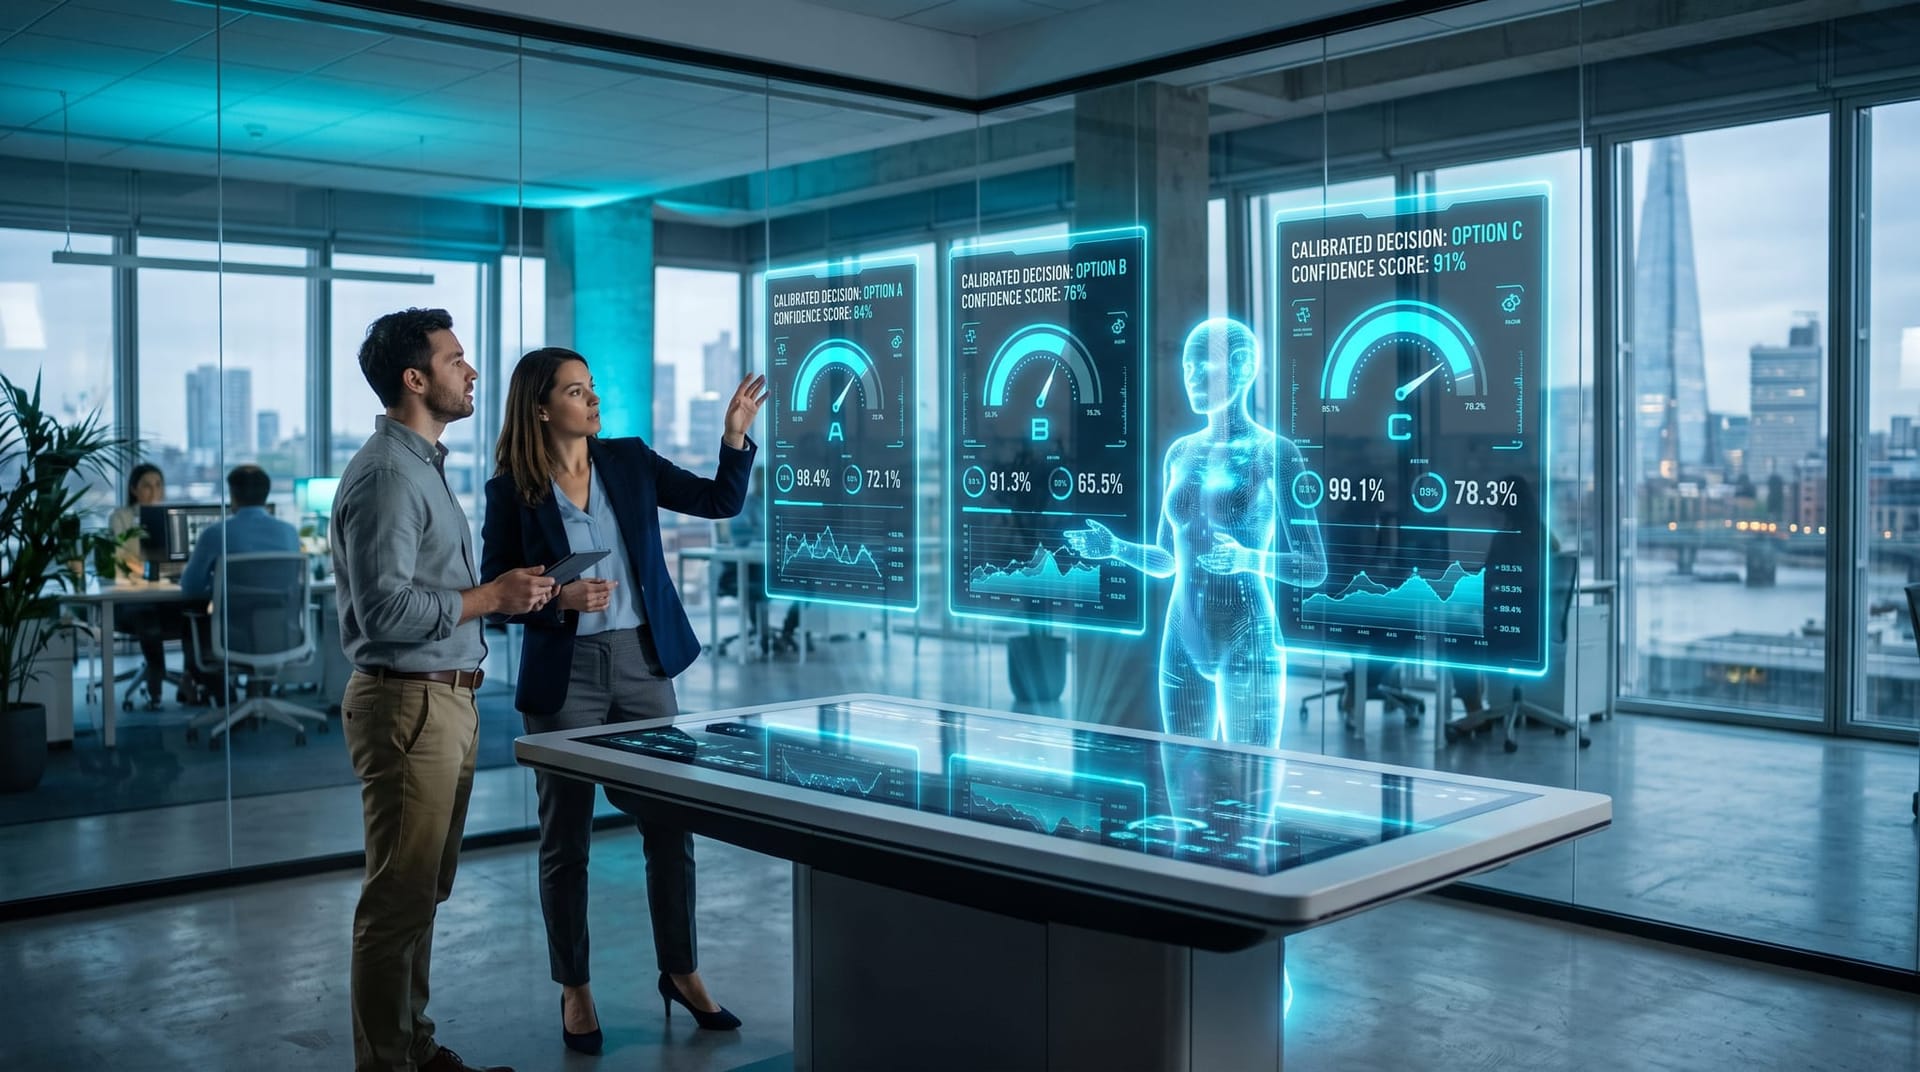
The takeaway for a business audience isn't which one “wins.” It's that, in the span of a week, calibrated decision-making went from a single hosted product to a category with an open training-free option and an open fast model — which means it's now something you can reasonably expect your AI Employee vendor to have an answer for.
How does a calibrated decision layer actually work?
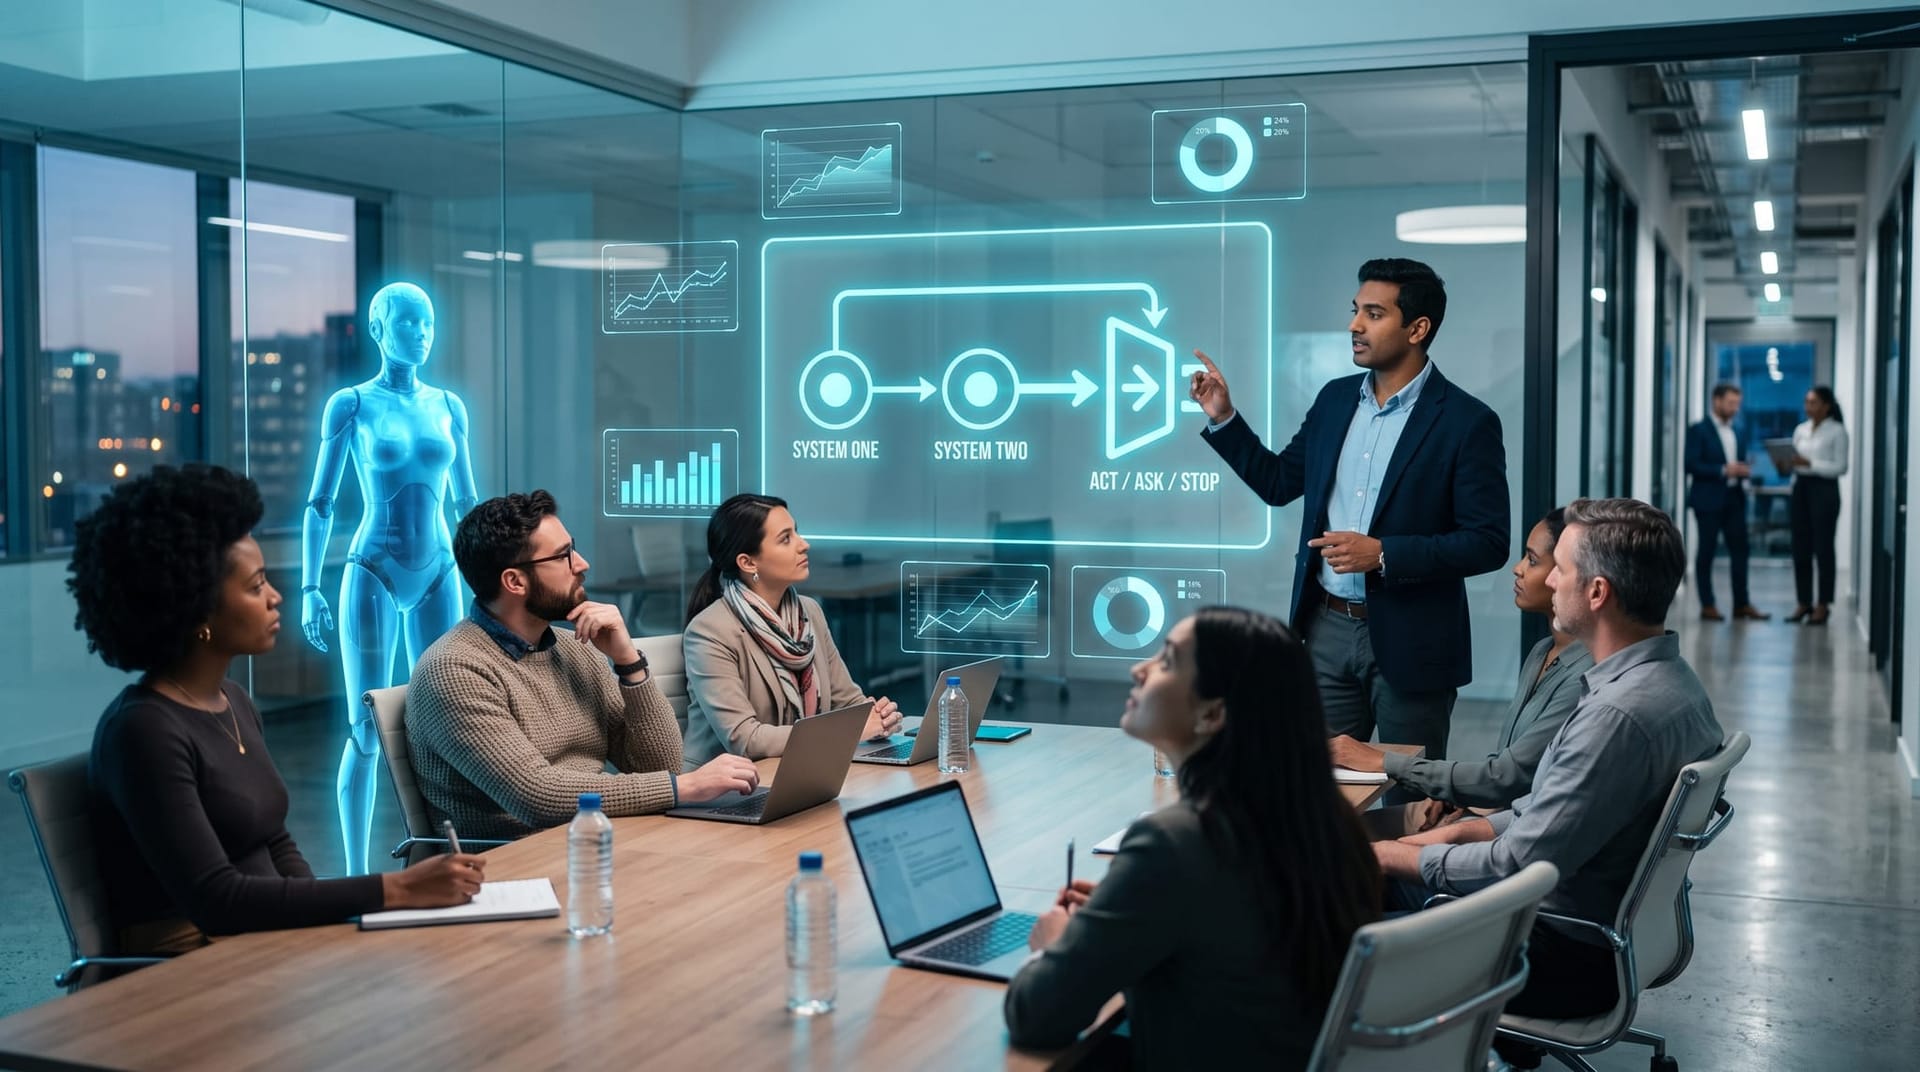
The clearest mental model is the “System One / System Two” split. Your big reasoning model — the one that drafts, plans, and explains — is System Two: powerful, slow, and prone to sounding confident even when it's guessing. A calibrated decision model is System One: a fast reflex that doesn't try to reason out loud, it just returns a typed answer and a number for how sure it is.
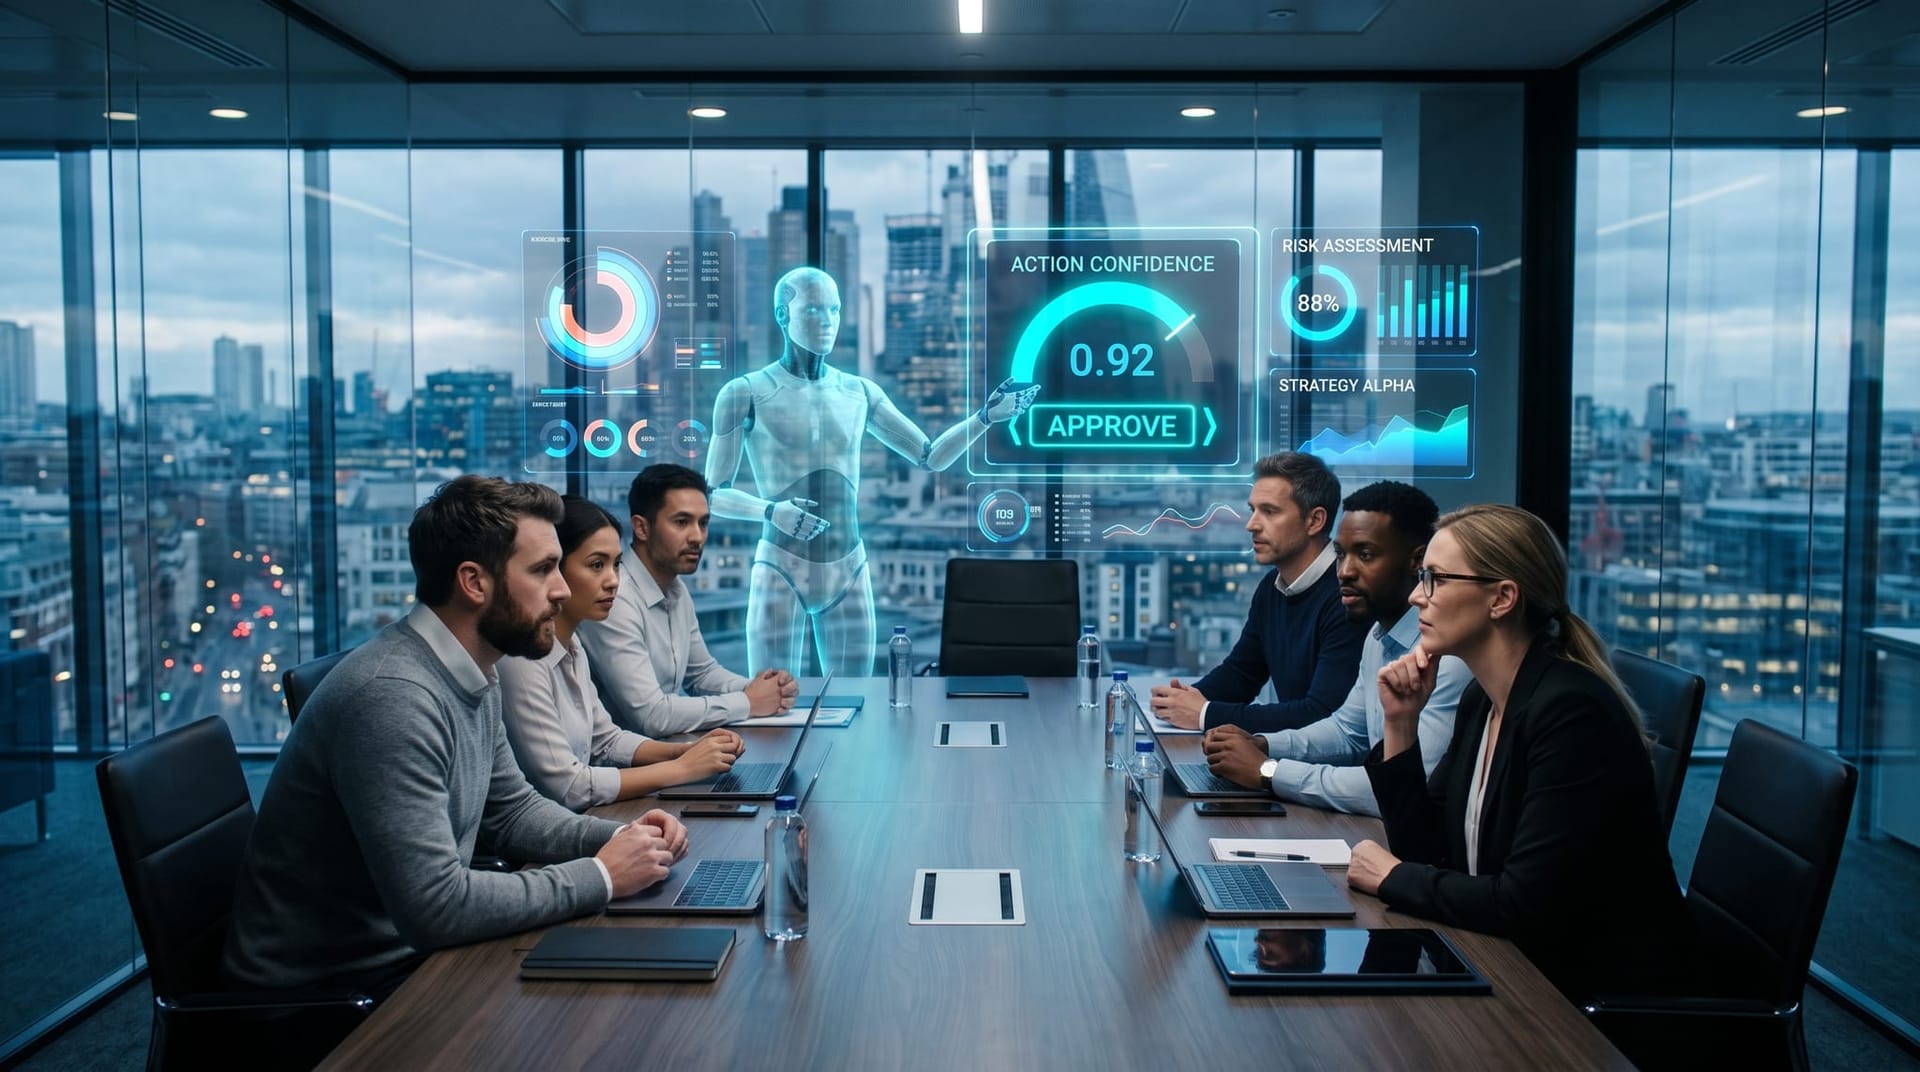
That number is what turns judgment into a control you can wire up. TypeSafe's own coding walkthrough shows the pattern cleanly: confidence-gated routing where “the bar rises with the stakes.” In their banking example, a balance check is allowed to proceed at 0.50 confidence, disputing a charge requires 0.70, a transfer needs 0.85, and closing an account demands 0.90. Below the bar, the action routes to a human (“confirm first”); at or above it, the agent acts. The threshold isn't the model's decision — it's yours, set per action according to how much a mistake costs.
Two design details matter for anyone evaluating this. First, these systems are typed on purpose: because the model returns a Choice or a Score or a boolean rather than a paragraph, the output can't drift into something your code can't parse — what TypeSafe calls “zero hallucinations,” which honestly means schema-matching is guaranteed, not that the answer is always correct. Second, the questions are independent — Jev's “speculative fan-out” evaluates many questions against the same state at once, which the guide reports runs modestly faster and cheaper than asking one at a time.
It's worth being precise about what this isn't. A decision model gates an action before it happens. That's different from the LLM-as-a-judge pattern, where a second model grades an output after the fact — useful for evaluation, but too late to stop a bad action. Gate-before and grade-after are complementary, not the same thing, and a serious AI Employee stack uses both.
Where does this fit in an AI Employee stack?
At Cloud Radix, we think about an AI Employee as three layers, not one model. There's the reasoning layer that figures out what to do. There's a decision/calibration layer that scores how sure it is about each concrete action. And there's a governance layer that enforces the rules regardless of what the model wants to do. The releases this month strengthen the middle layer — and that's precisely the layer most vendors have been hand-waving past.
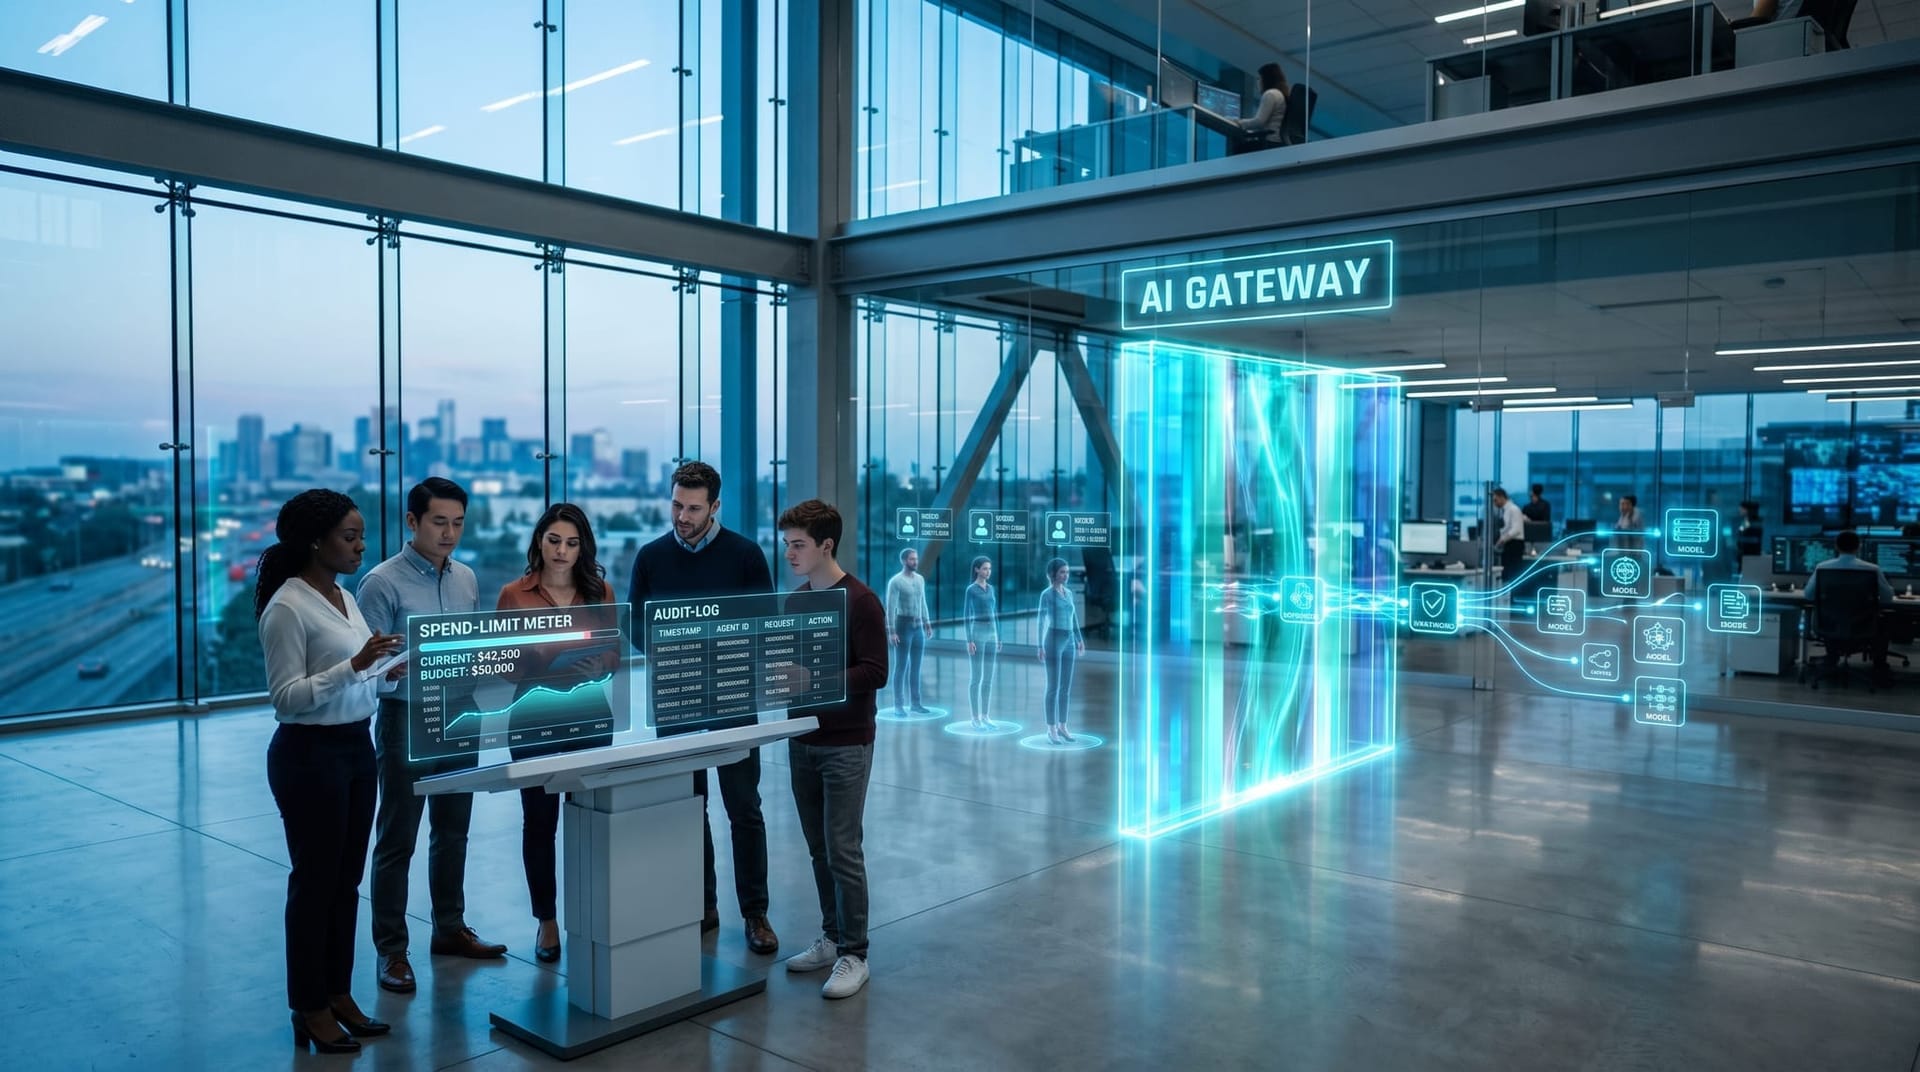
A calibrated confidence score is the signal that makes the other two layers work. It's what an escalation system needs to decide when to ask a human: without a trustworthy number, “escalate when unsure” is just a vibe. And it's what a governance layer enforces against. In our Secure AI Gateway framing, the gateway is where the propose-vs-act gate actually lives: every action an agent proposes carries its confidence score and its intended effect, and the gateway checks that score against the threshold you set for that workflow before anything touches a real system. The decision model produces the number; the gateway decides whether the number is good enough to let the action through — and logs it either way.
That division of labor is the whole point. You should not have to trust that the model is being careful. You should be able to verify, per action, that a calibrated score cleared a threshold you chose, and pull the audit log to prove it. This is the same reasoning we've laid out about the agent control plane becoming the real buying decision — the model matters far less than the layer that governs it. To be clear, the vendor checklist and the “gateway enforces the gate” architecture are our editorial framing, not claims made by TypeSafe, Nokia, or Contrastive-LM. But this month's releases are what make that architecture buildable off the shelf rather than something every team has to invent.
What should a Northeast Indiana operator ask before flipping “propose” to “act”?
You don't need to read a single benchmark paper to use any of this. You need to ask the right questions before you let an AI Employee take its first real action inside your business. Whether you're a DeKalb County manufacturer, an Allen County law firm, or a Fort Wayne home-services company, the trust wall is the same — and so is the checklist:
- Does each action carry a confidence score? If the vendor can't show you a number attached to a specific proposed action, there is no gate — there's just a model doing whatever it decided.
- Is the score calibrated, or is it vibes? Ask how the confidence is derived and whether it's been checked against real accuracy. Raw model self-confidence is known to be unreliable; a debiased or purpose-trained score is the point of this whole category.
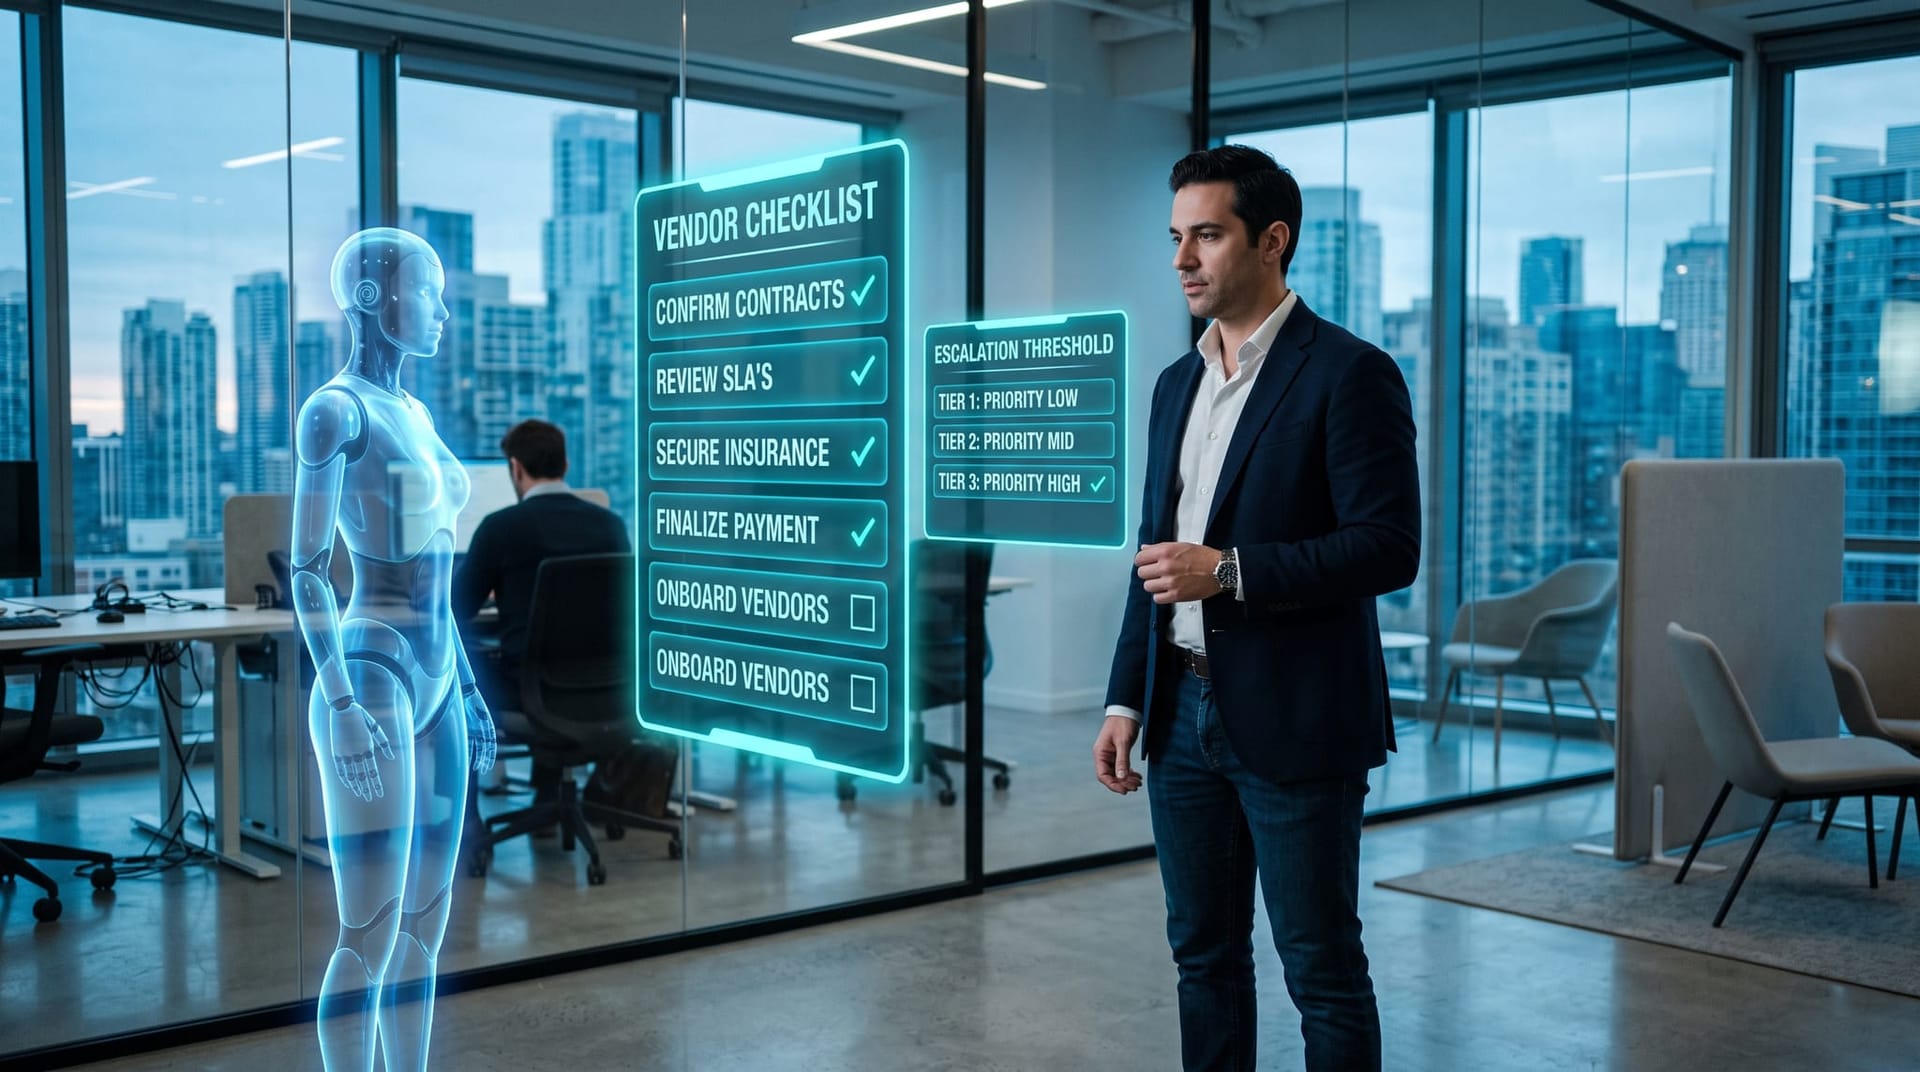
- Who sets the escalation threshold, and can we tune it per workflow? A refund and a balance check should not share a bar. You should be able to set 0.90 for irreversible actions and 0.60 for cheap, reversible ones.
- What happens below the threshold? “Escalate to a human” should mean a specific person, a specific queue, and a specific SLA — not a log entry nobody reads.
- Is every gated decision logged for audit? You want a record of what the agent proposed, the score, the threshold, and the outcome — for the ones it acted on and the ones it escalated.
- Are you locked into one hosted model? With open options like AnyJev and CLM-8B now available, “we can only do this on our proprietary endpoint” is a fair thing to push on.
- Can we start on one workflow and expand? The right answer is yes. Anyone insisting you flip everything to autonomous at once is selling risk, not capability.
If a vendor fumbles these, that's your answer. This is the same rebuild-or-patch judgment we walk through in our piece on AI agent reliability: a system without a real decision-and-gate layer isn't one you patch into trustworthiness later.
Where should a Fort Wayne business start?
Don't try to make your whole operation autonomous. Pick one high-consequence, high-volume workflow where a human is currently the bottleneck on every item — accounts-receivable follow-up, new-lead intake triage, or after-hours phone handling are common ones for Northeast Indiana service businesses. Require calibrated gating on that one workflow: the AI Employee proposes an action, a decision layer scores it, and only actions above the threshold you set proceed automatically. Everything below the bar routes to a named person.
Run it that way for a few weeks and watch two numbers: how many actions cleared the gate automatically (the labor you actually saved) and how many escalations turned out to be genuine catches (the mistakes you avoided). If the automatic rate is healthy and the escalations are catching real problems, you raise the volume or lower the bar deliberately. If not, you tighten it. Either way you're tuning a dial you can see — which is a very different posture than hoping a model behaves. Once that first workflow earns trust, the second one is a configuration change, not a leap of faith.
Ready to move past draft-only?
Cloud Radix builds AI Employees for businesses across Fort Wayne and Northeast Indiana with the decision-and-gate architecture described here baked in — calibrated confidence on each action, thresholds you set per workflow, and a Secure AI Gateway that enforces and logs every gate. If you've been stuck letting AI draft but never act, that's the exact wall we help operators cross, one workflow at a time. Explore AI Employees for Fort Wayne businesses, or see the full range of AI Employees we deploy. We'll help you pick the first workflow worth trusting — and prove it out before you scale it.
Frequently Asked Questions
Q1.What is a calibrated AI decision model?
It's a small model whose job is to return a typed decision — a choice, a score, or a true/false — plus a confidence number between 0 and 1, rather than free-form text. "Calibrated" means the confidence is meant to actually track how often the model is right, so the number is trustworthy enough to gate an action. The releases from TypeSafe AI, Nokia, and Contrastive-LM in September 2026 are all examples of this category.
Q2.Can I trust an autonomous AI agent to take real actions in my business?
You can trust it for specific actions, under specific conditions — not blanket "full autonomy." The practical approach is to require a calibrated confidence score on each proposed action and set a threshold per workflow: high-stakes, irreversible actions need a high bar, cheap reversible ones can use a lower one. Anything below the threshold routes to a human. That way autonomy is earned action-by-action, with an audit log, rather than granted all at once.
Q3.What's the difference between Jev, AnyJev, and CLM-8B?
They're three products in the same category, made by different teams. TypeSafe AI's Jev is a hosted, proprietary model (no downloadable weights). Nokia's AnyJev is an open-source Python library that adds calibration to any open LLM you already run, without training. Contrastive-LM's CLM-8B is an open model with downloadable weights, built to score actions quickly on a single GPU. They are not interchangeable, and the right choice depends on whether you value a turnkey API, freedom from one vendor, or open self-hosting.
Q4.Is "System One" AI just marketing?
It's a useful analogy, not a technical guarantee. "System One" refers to a fast reflex layer that returns a typed answer and a confidence score, as opposed to a slow "System Two" reasoning model that thinks out loud. The value isn't in the label — it's in the calibrated number attached to each action, which is what lets your system decide whether to proceed, review, or stop.
Q5.Are the vendor speed and cost claims reliable?
Treat them as directional. Figures like "9x faster" or "444.6x cheaper" come from vendor-run benchmarks on specific tasks, and the gap changes a lot depending on the workload — CLM-8B's 9x figure, for instance, shrinks to under 2x on less cache-friendly tasks. TypeSafe itself notes it "cannot prove the price is unsubsidized." Use the claims to understand the direction of the improvement, then validate on your own workflow before committing.
Q6.Do calibrated AI decision models make sense for a small Fort Wayne or Northeast Indiana business?
Yes — arguably more so than for a large enterprise. If you run a lean DeKalb County or Allen County operation, the labor an AI Employee saves matters proportionally more, and so does avoiding one costly wrong action. The path is the same one we'd recommend to any local operator: pick a single high-consequence, high-volume workflow, require a calibrated confidence gate on it with a threshold you set, and route anything below the bar to a named person. You capture the labor savings on the clear-cut cases without betting the business on full autonomy.
Q7.How does Cloud Radix use calibrated decision models in AI Employees?
We treat the calibrated confidence score as the signal that drives our propose-vs-act gate. An AI Employee proposes an action, a decision layer scores its confidence, and our Secure AI Gateway checks that score against a threshold you set for that workflow before the action touches any real system — logging every decision for audit. The specific decision model can be a hosted or open option; the architecture around it is what makes the action trustworthy.
Sources & Further Reading
- MarkTechPost: marktechpost.com/2026/09/23/contrastive-lm-releases-clm-8b — Contrastive-LM Releases CLM-8B, an Open “System One” Model That Scores Agent Actions Up to 9x Faster Than Jev.
- MarkTechPost: marktechpost.com/2026/09/23/nokia-open-sources-anyjev — Nokia Open-Sources AnyJev, a Training-Free Layer That Turns Any Open LLM Into a Calibrated Decision Model.
- MarkTechPost: marktechpost.com/2026/09/19/typesafe-ai-releases-jev — TypeSafe AI Releases Jev.
- MarkTechPost: marktechpost.com/2026/09/23/a-coding-guide-to-typesafe-ai-jev — A Coding Guide to TypeSafe AI Jev.
- CIO: cio.com/article/4107315/agentic-ai-in-2026-more-mixed-than-mainstream — Agentic AI in 2026: More Mixed Than Mainstream.
- arXiv: arxiv.org/abs/2502.11028 — Mind the Confidence Gap: Overconfidence, Calibration, and Distractor Effects in Large Language Models.
Pick the First Workflow Worth Trusting
We'll help your Fort Wayne or Northeast Indiana business move one high-consequence workflow from “propose” to “act” — with calibrated confidence gates, thresholds you set, and a Secure AI Gateway that logs every decision.