There's a certain kind of demo that makes a business owner fall in love with AI and a certain kind of Tuesday that breaks the romance. The demo goes perfectly because the question was clean. The Tuesday goes badly because a real customer asked something slightly off-script, and the chatbot — confident as ever — made something up.
If you want to understand why that happens, start with an uncomfortable premise that a lot of vendors would rather you didn't dwell on: a raw large language model does not “reason” the way a human does. It completes patterns. That isn't a slur, and it isn't a prediction that AI is a fad. It's a description of the machinery — and once you accept it, the whole question of which AI deployments succeed and which ones blow up starts to make a lot more sense.
In a sharp piece for MIT Technology Review, machine-learning researcher Thore Graepel — a former member of DeepMind's AlphaGo team, now chair of machine learning at University College London — argues that today's models are extraordinary “System 1” pattern-completers that we keep mistaking for deliberate thinkers. We agree with the diagnosis. We just draw the opposite conclusion about what to do next. The businesses that get burned are the ones that bolt a naked model onto a workflow and expect judgment. The ones that win engineer around the limitation. At Cloud Radix, that's the entire design philosophy behind an AI Employee: it's a system, not a model.
Key Takeaways
- A raw LLM performs fast, associative pattern completion — not auditable, step-by-step reasoning. Treating it as if it does is the root cause of most failed deployments.
- Controlled studies show model accuracy drops sharply when problems are perturbed in ways that shouldn't matter to a genuine reasoner — one Apple study measured drops of up to 65% from a single irrelevant sentence.
- The “chain of thought” a model prints is often a post-hoc story, not a faithful record of how it reached the answer.
- Hallucination is a structural byproduct of how models are trained and graded, not a bug that will quietly disappear.
- Reliability comes from the system wrapped around the model — retrieval grounding, tool use, verification, policy guardrails, and a human escalation path — not from a bigger model alone.
Do LLMs Actually Reason, or Just Pattern-Match?
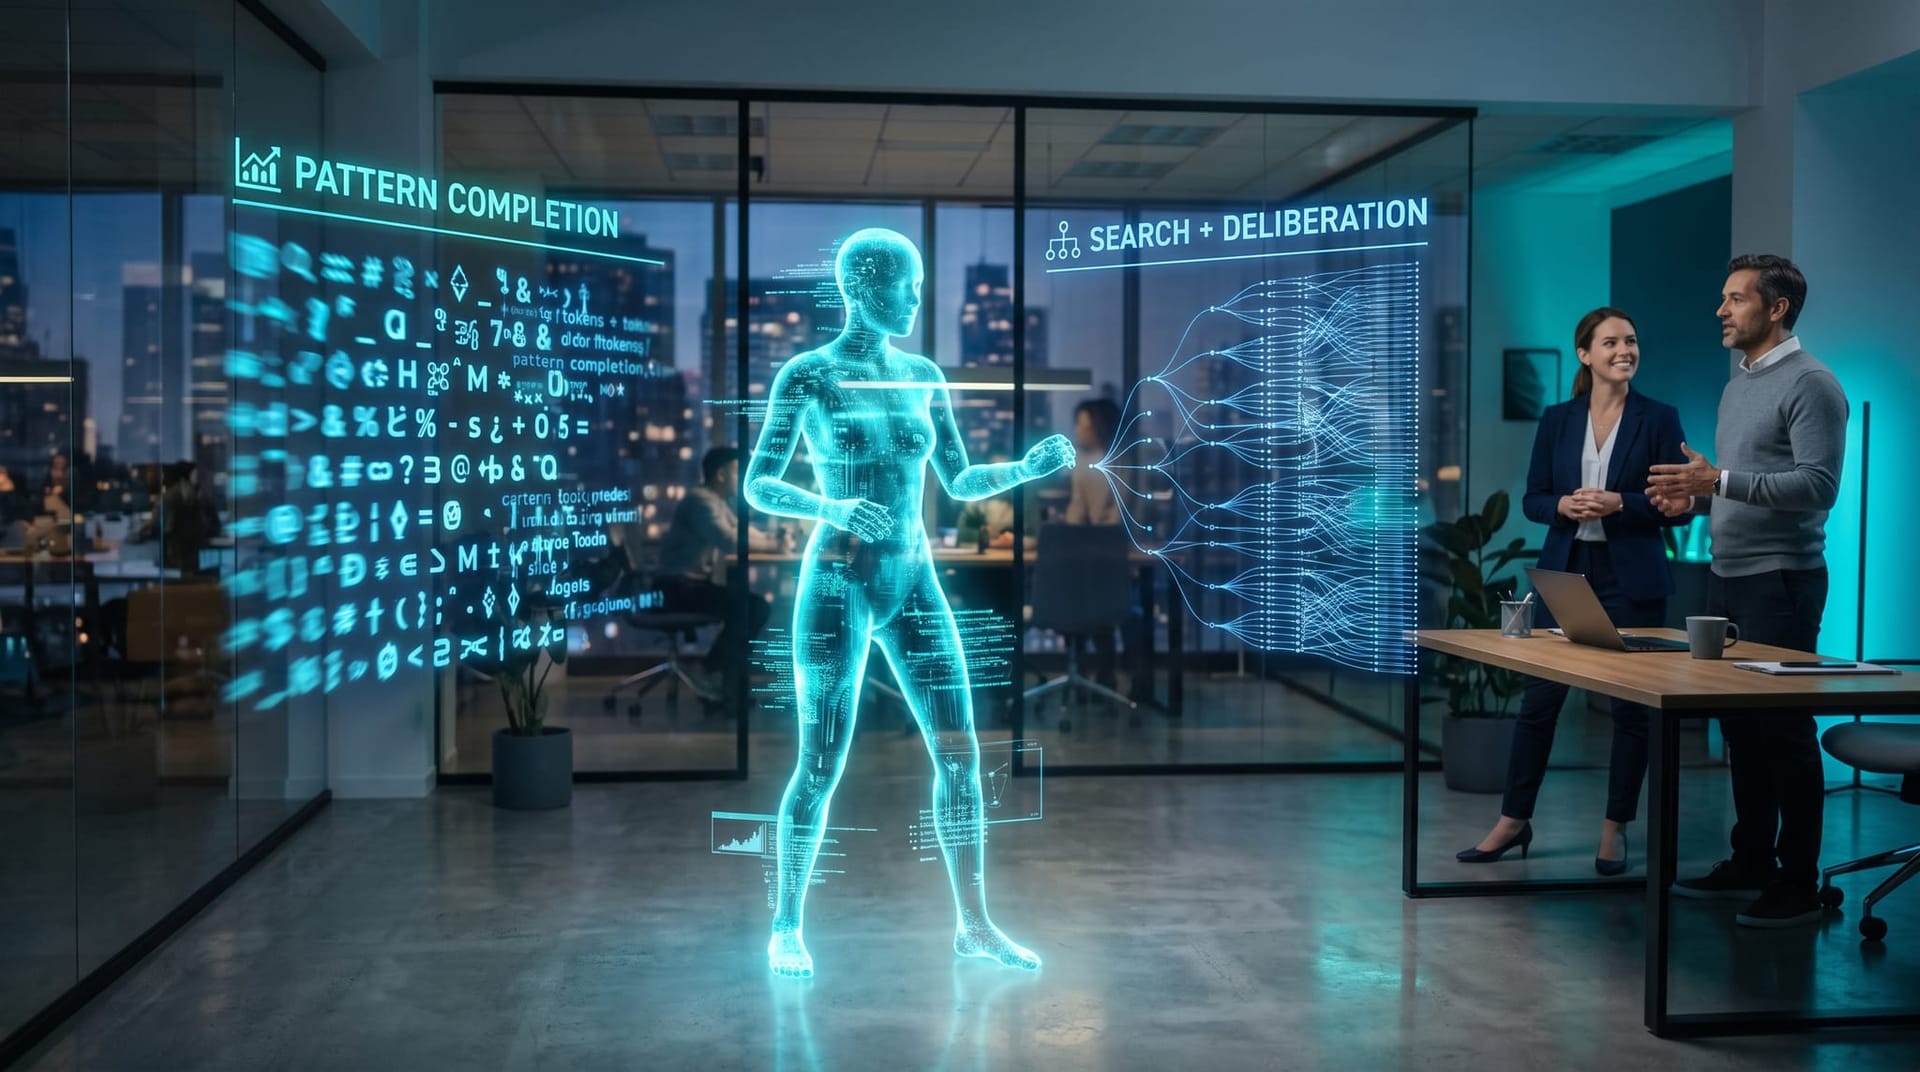
Graepel's framing borrows from the familiar split between fast, intuitive “System 1” thinking and slow, deliberate “System 2” thinking. His argument is that an LLM is almost pure System 1: it picks the next token, repeatedly, in a way he describes as “fast, associative, and surprisingly good pattern completion.” Even the chain-of-thought tricks that make models look more deliberate are, in his words, “the same next-token prediction process, iterated for longer.” Stretching the output doesn't install a new kind of cognition; it runs the same engine for more cycles.
He contrasts this with AlphaGo, the system he helped build. When AlphaGo played its famous Move 37 against Lee Sedol in 2016 — a move its own policy network rated as roughly a one-in-10,000 choice for a human — it wasn't pattern-matching from a library of games. It searched. It built a game tree with thousands of branches, weighed future consequences, and kept an auditable record of what it had considered before committing. Lee Sedol's reaction afterward — “surely, AlphaGo is creative” — was a response to something that genuinely deliberated. Graepel's point is that modern chatbots, for all their fluency, lack exactly that: no explicit “open ledger” of hypotheses and confidence, no clean separation between what the model knows and how it processes, and a tendency to “concoct” reasoning steps after the fact — “reaching an answer by one route but reporting another.”
That last part matters enormously for business use, so sit with it. The tidy, numbered explanation a model gives you for its answer is not necessarily the path it took. It's a plausible-sounding narrative generated alongside the answer. For a brainstorm, who cares. For a quote to a customer, a compliance decision, or a medical intake summary, a confident explanation that doesn't reflect the actual process is worse than no explanation at all — because it invites trust it hasn't earned. This is a big part of why we've written before about the 85%/5% trust gap we wrote about earlier: leaders say they want AI everywhere, but very few will hand it an unsupervised, consequential task. The instinct is correct. The machinery underneath justifies the caution.
What Does the Evidence Say About LLM Reasoning Limits?
This isn't just one researcher's philosophical take. It shows up in controlled testing, repeatedly, in ways you can measure.
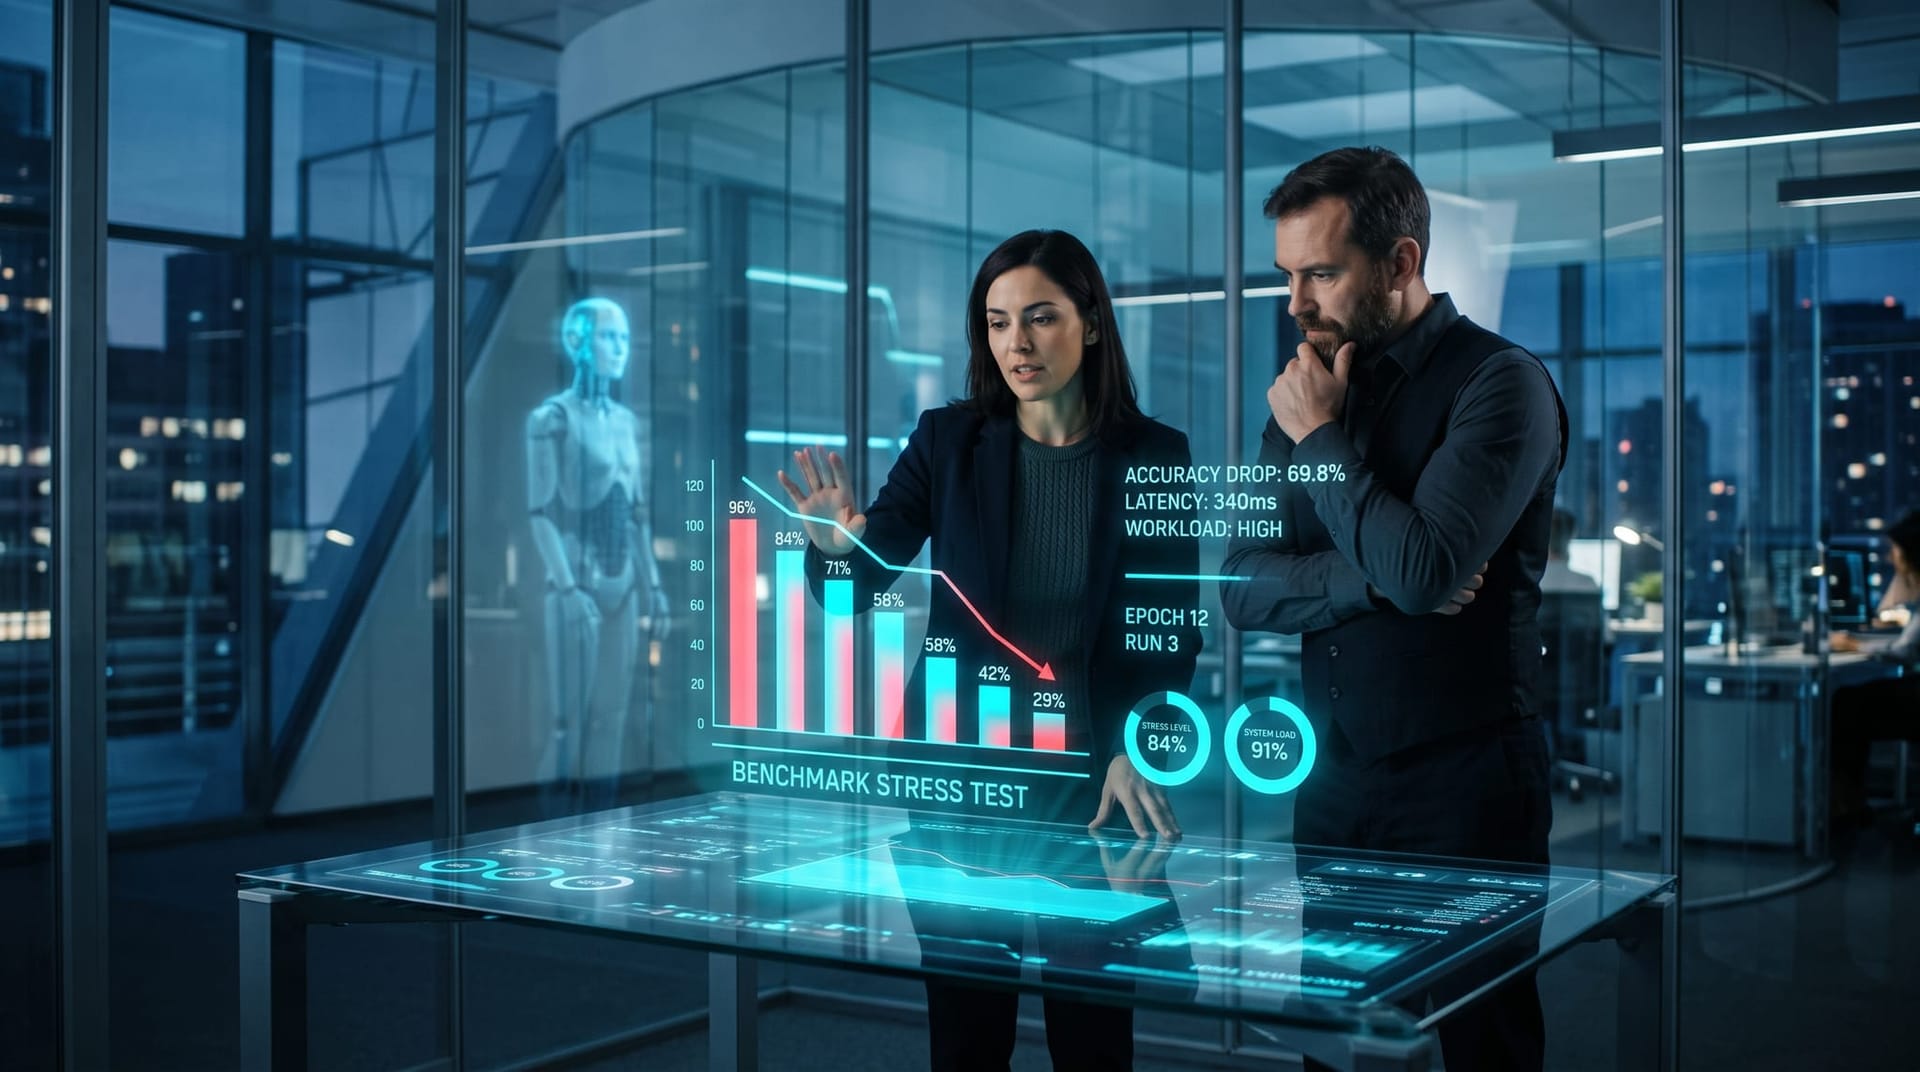
The clearest example comes from Apple's GSM-Symbolic study, which built a benchmark that could re-skin the same grade-school math problems with different numbers, different names, and extra clauses. A true reasoner shouldn't care whether the person in the word problem is named Sophie or Sam. But the models did care. Accuracy fell when only the numbers changed, and it fell further when superficial surface details changed. Most striking: when the researchers inserted a single clause that looked relevant but added nothing to the actual math — their “no-operation” variant — performance dropped by as much as 65% across the state-of-the-art models they tested. That is the signature of pattern-matching, not reasoning. The model latches onto the shape of the problem and gets thrown by noise a thinking person would ignore.
Anthropic's alignment team found a parallel problem with the explanations models give. In research on chain-of-thought faithfulness, they slipped models a hint toward an answer and then checked whether the model admitted using it. Often it didn't. In their testing, Claude 3.7 Sonnet acknowledged a hint it had clearly used only about 25% of the time, and models frequently “constructed fake rationales for why the incorrect answer was in fact right.” The printed reasoning, in other words, is not a reliable window into the process — which lines up exactly with Graepel's point about post-hoc rationalization.
| What we'd want from a reasoner | What the evidence shows about raw LLMs |
|---|---|
| Stable answers when irrelevant details change | Accuracy drops up to 65% from a single irrelevant clause (Apple GSM-Symbolic) |
| Explanations that reflect the real process | Hints influencing the answer were verbalized only ~25% of the time (Anthropic) |
| A record you can audit after the fact | No explicit ledger of hypotheses, evidence, or confidence (Graepel, MIT Technology Review) |
| Graceful "I don't know" under uncertainty | Models trained to guess confidently rather than abstain (see below) |
None of this means the models are useless — far from it. It means their failure modes are predictable and specific. And predictable failure modes are something an engineer can design around. Unpredictable ones aren't. The teams that struggle are usually the ones carrying a pile of invisible AI technical debt that builds up in prompts, retrieval, and evaluation — debt that stays hidden right up until a perturbed, real-world input exposes it.
Why Do Raw LLMs Hallucinate — and Why Do Benchmarks Make It Worse?
If a model is a pattern-completer, a fabricated-but-plausible answer isn't a malfunction. It's the system working as designed, applied to a case where the pattern doesn't actually have a grounded answer behind it.
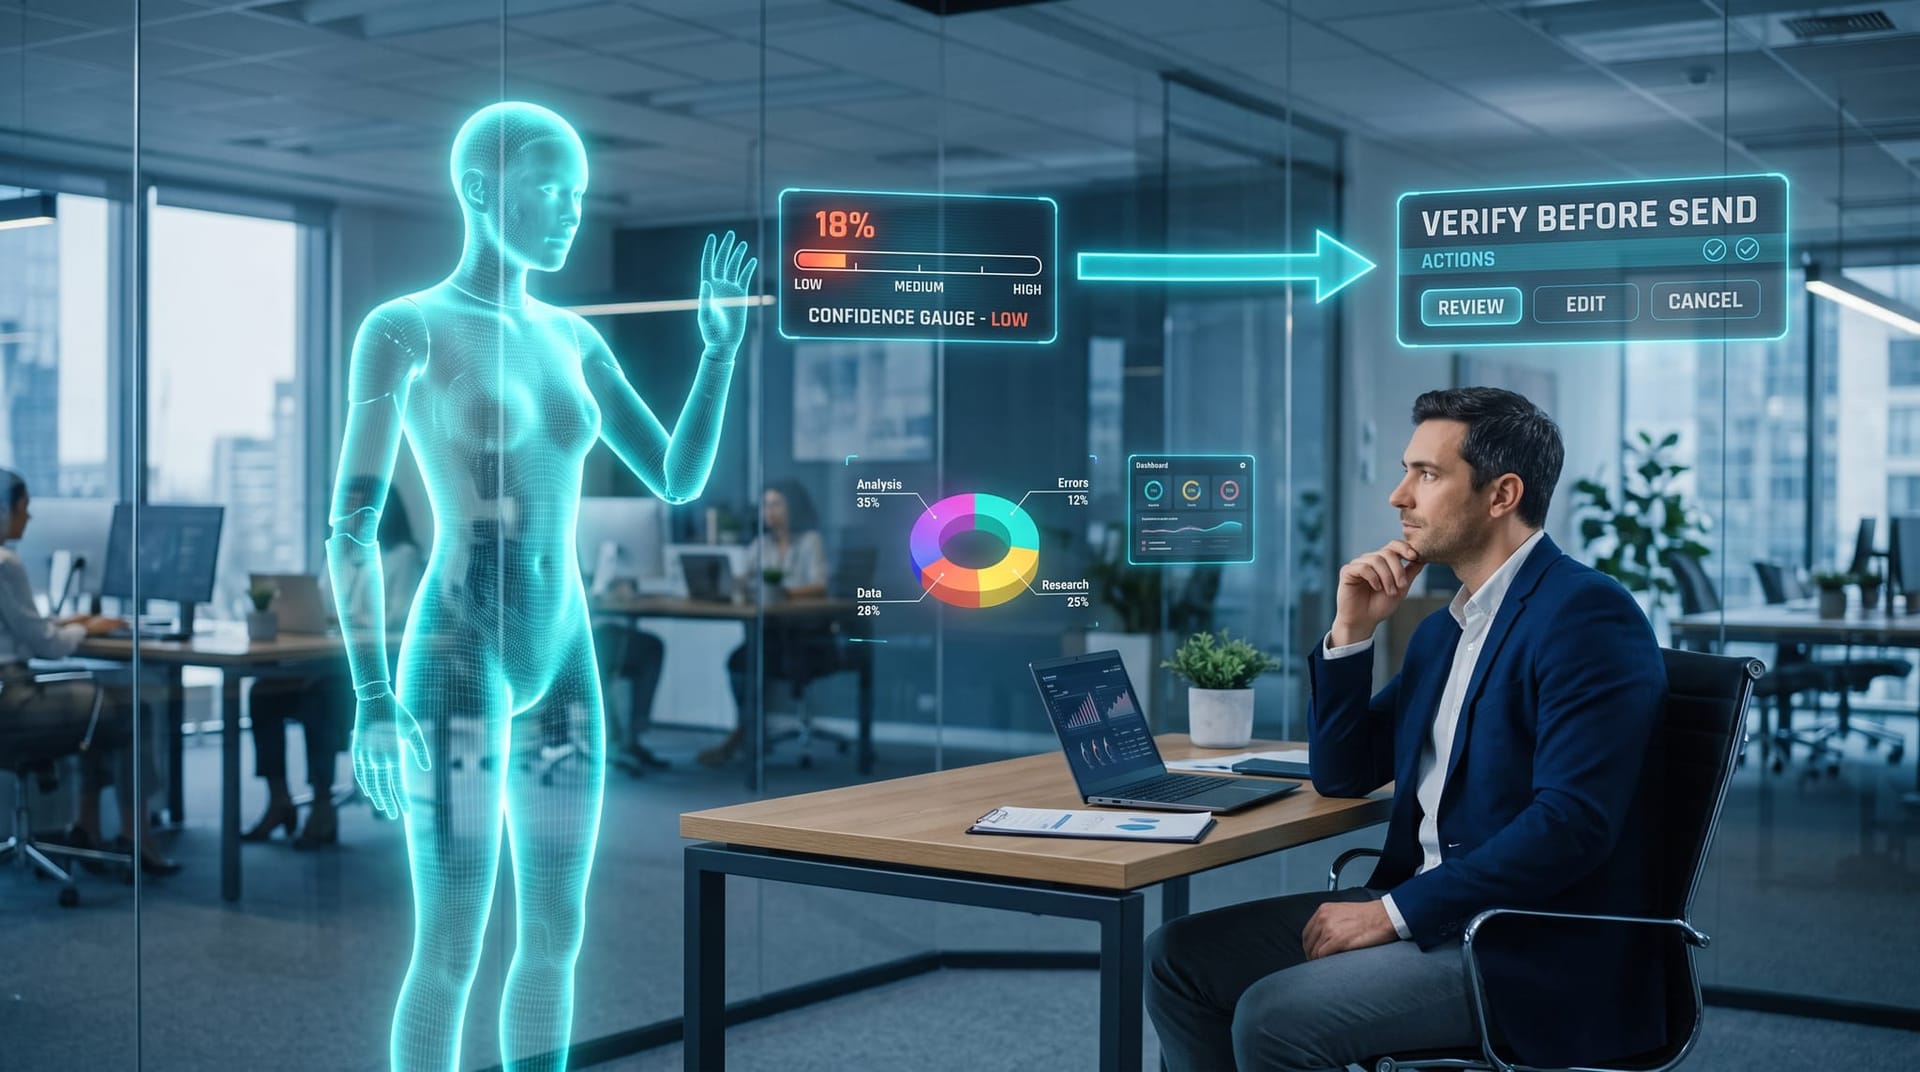
A 2025 paper from OpenAI and Georgia Tech, on why language models hallucinate, makes this concrete from the training side. The authors argue that hallucinations are “natural statistical errors” that arise because generating correct text is harder than merely recognizing correct text, and — crucially — because the way we grade models rewards the wrong instinct. Most benchmarks and post-training pipelines reward a confident guess over an honest “I'm not sure.” A model that abstains when uncertain scores worse on the test than one that bluffs and occasionally gets lucky. So we train relentless test-takers. The researchers note that letting models abstain when uncertain measurably reduces hallucination — but that only helps if the surrounding system actually lets the model say “I don't know” and does something useful with that signal.
For a business, the lesson is blunt: a bare chatbot is optimized to always have an answer, and “always has an answer” is a catastrophic property for anything involving money, law, health, or a customer's trust. The fix is not to scold the model. The fix is to build a system where “I'm not confident” triggers a different path — retrieval, a tool call, or a handoff — instead of a confident fabrication. We've argued this at length in our piece on why the context-layer paradox means reliability fixes backfire when they're bolted on without the right grounding underneath.
What's the Difference Between a Model and a System?
Here's where we part ways with the doom reading of Graepel's article. “LLMs don't reason” is true, and it is not a reason to stay on the sidelines. It's a spec. It tells you exactly what scaffolding the model needs.
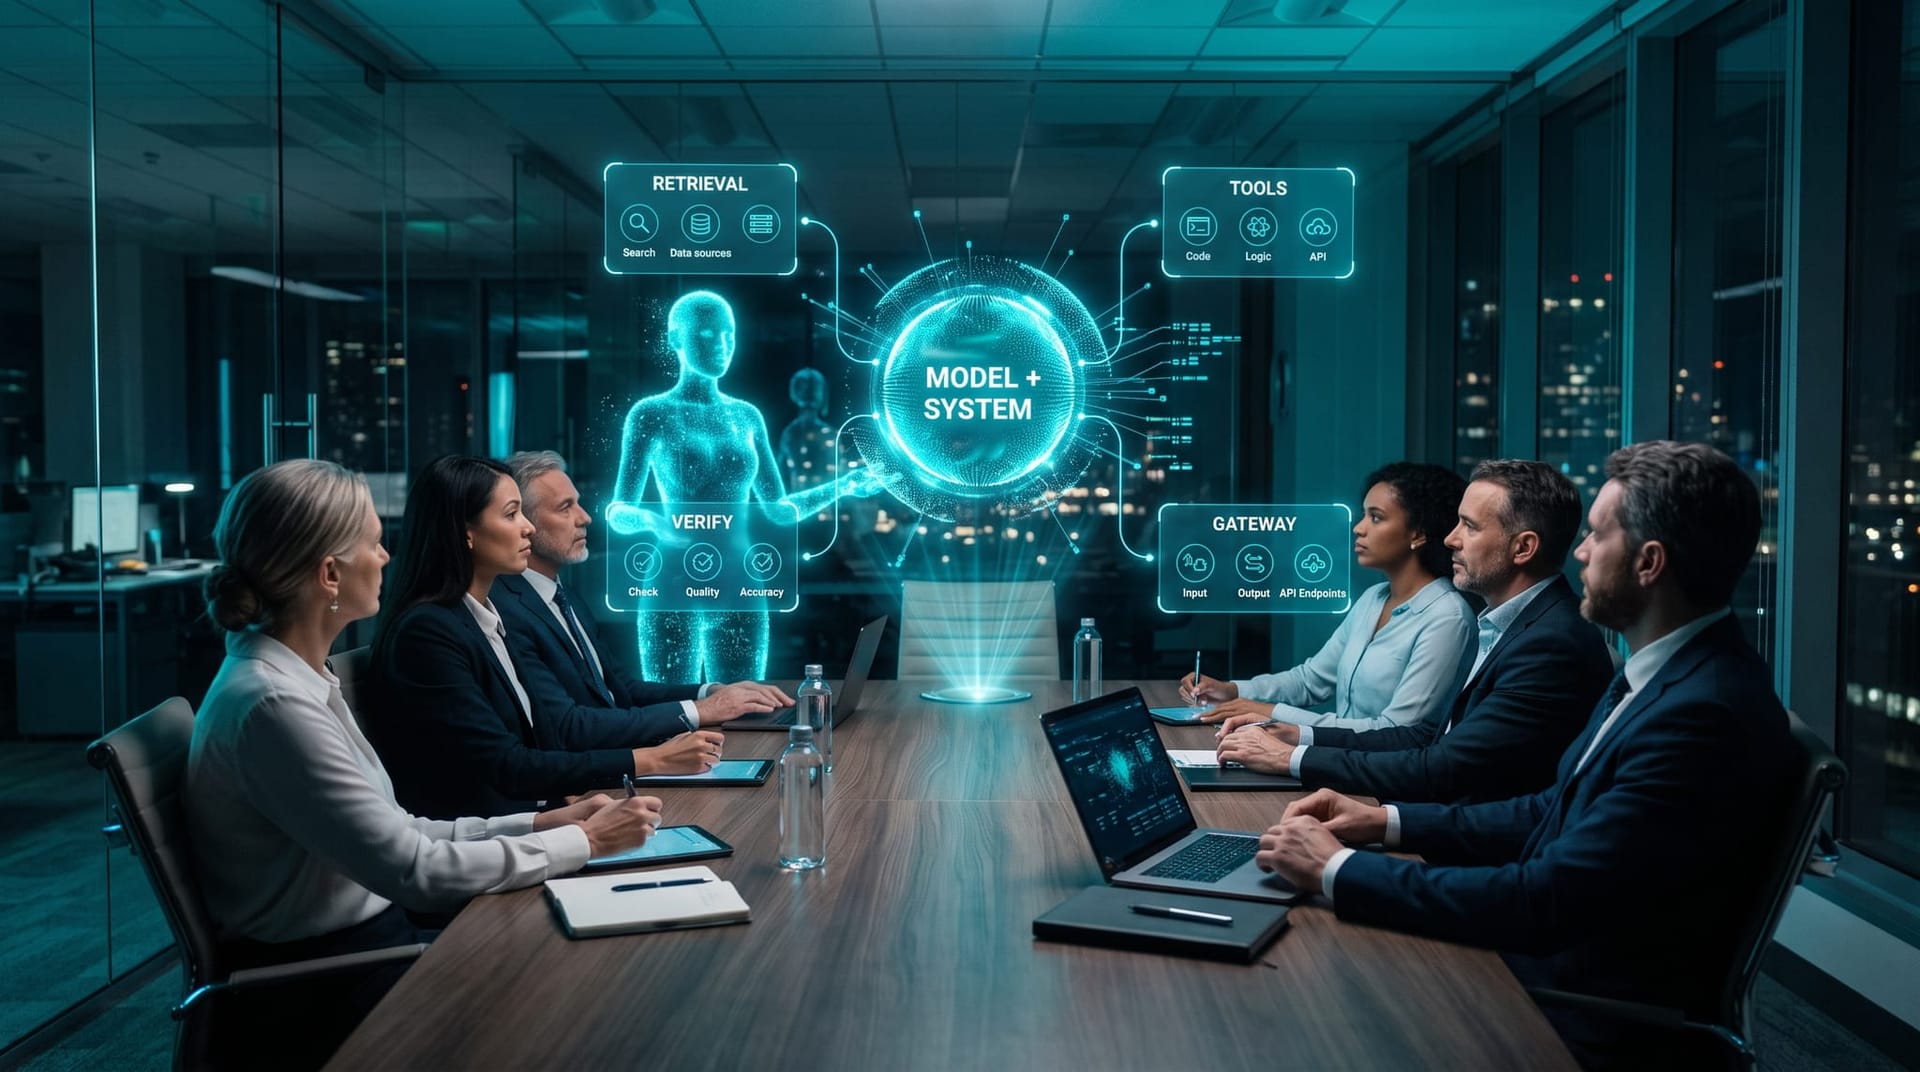
The broader AI research community has been converging on this for a couple of years. Berkeley's AI Research lab described the shift from models to compound AI systems back in early 2024, observing that state-of-the-art results increasingly come from systems with multiple components — retrieval, tools, control flow, verification, external data — rather than from a single monolithic model. The model is one component. The system is what delivers the outcome. Reliability, auditability, and trust are properties you build at the system level, because — as the evidence above shows — you can't get them from the weights alone.
| Dimension | A raw LLM (just a model) | An AI Employee (a system) |
|---|---|---|
| Knowledge | Frozen in training weights; blends fact and guess | Grounded in your current data via retrieval, cited back |
| Actions | Describes what it would do | Executes through governed, permissioned tools |
| Uncertainty | Guesses confidently | Detects low confidence and escalates |
| Explanation | Post-hoc narrative, often unfaithful | Logged inputs, tool calls, and outputs you can audit |
| Failure mode | Silent, confident, unpredictable | Caught at a verification or policy checkpoint |
| Oversight | None by default | Human-in-the-loop on consequential steps |
This distinction isn't academic, and the cost of ignoring it is measurable. In Carnegie Mellon's TheAgentCompany benchmark, researchers dropped leading agents into a simulated company and gave them 175 real professional tasks across software, finance, HR, and administration. The best performer completed only about 30% of them autonomously, tripping over exactly the things a pattern-completer would trip over: social nuance, messy interfaces, and a tendency to take shortcuts. That's the ceiling for a “smart model, no system” approach. It's also the number that should make any vendor promising fully autonomous, hands-off AI for your whole back office slow down and explain their architecture.
How Does Cloud Radix Engineer AI Employees Around the Reasoning Gap?
Every design decision we make assumes the model is a brilliant, unreliable System-1 engine — and then wraps it in the System-2 machinery it lacks on its own. Concretely:
- Retrieval grounding. The AI Employee answers from your documents, your pricing, your policies — retrieved fresh at query time and cited — rather than from whatever pattern the weights suggest. This is what converts “sounds plausible” into “verifiably from your source of record.”
- Tool use over free text. When a task needs a real action — booking, looking up an order, pulling a balance — the system calls a governed tool and uses the structured result, instead of letting the model narrate an answer it can't actually verify.
- Verification steps. Consequential outputs pass through checks — schema validation, policy rules, a second-pass review — before they reach a customer. The model proposes; the system disposes.
- Policy guardrails via the secure AI gateway. Our secure AI gateway sits between the model and your systems, enforcing what data it can touch, what actions it can take, and what it must never do — so a confident wrong answer can't quietly become a confident wrong action.
- A human escalation path. When confidence is low or the stakes are high, the AI Employee hands off instead of guessing. We designed this deliberately; it's why we wrote a whole piece on knowing when to escalate to a human. The OpenAI hallucination research is the technical justification: give the model a real way to abstain, and the error rate falls.
The through-line is that we don't ask the model to be something it isn't. We ask it to do the one thing it's genuinely excellent at — fast, fluent pattern completion over grounded context — and we build everything else in the surrounding system. That's also why we insist on measurement. You can't manage a reliability property you don't track, which is the whole reason we're public about how we measure AI Employee performance: task completion, escalation rate, grounded-citation rate, and error rate on real traffic — not benchmark scores on clean questions that look nothing like a bad Tuesday.
A Northeast Indiana Lens
Most of the businesses we work with across Fort Wayne, DeKalb County, and the wider Northeast Indiana region aren't running AI research labs. They're professional-services firms, clinics, manufacturers, and home-services operators who need a specific job done reliably — answer the phone after hours, qualify a lead, draft a first-pass quote, chase a document. For them, the “LLMs don't reason” debate isn't abstract. It's the difference between an AI that quietly invents a price and one that pulls the real number, cites it, and escalates when it's unsure. We'd rather deploy a narrower AI Employee that's honest about its limits than a flashy one that's confidently wrong in front of your customers. In our experience, that's the trade every serious operator makes once they've seen both.
Deploy AI That's Built Around the Limitation, Not in Denial of It
If you've been burned by a chatbot that sounded brilliant in the demo and improvised in production, the problem probably wasn't the model — it was the absence of a system around it. Cloud Radix builds AI Employees the other way around: grounded, governed, verified, and escalation-aware by default, so the model's pattern-matching strength works for you and its reasoning gap is covered by design. If you want to see what that looks like for a specific workflow in your business, take a look at our AI Employees service or get in touch. We'll tell you honestly where an AI Employee will thrive — and where a human still needs to hold the pen.
Frequently Asked Questions
Q1.Do large language models actually reason?
Not in the deliberate, step-by-step sense humans mean by the word. As researcher Thore Graepel argues in MIT Technology Review, today's LLMs are powerful pattern-completers — "System 1" engines that predict the next token — rather than systems that construct and audit a line of reasoning. They can produce reasoning-like text, but studies show that text is often a story generated alongside the answer, not a faithful record of how the answer was reached.
Q2.If LLMs just pattern-match, are they safe to use in business?
Yes — within a system designed for their limits. The failure modes are specific and predictable: they guess confidently, they're thrown by irrelevant details, and their explanations can be unfaithful. A well-built AI Employee compensates with retrieval grounding, governed tool use, verification checks, policy guardrails, and a human escalation path. The danger is using a bare model for consequential tasks with none of that scaffolding.
Q3.What does "an AI Employee is a system, not a model" mean?
The model is one component. The system is everything around it: the retrieval layer that grounds answers in your real data, the tools that let it take verified actions, the checks that catch bad outputs, the gateway that enforces policy, and the handoff that routes uncertain cases to a person. Berkeley's AI Research lab calls this a "compound AI system," and it's where reliable, auditable results actually come from.
Q4.Why do AI chatbots make things up (hallucinate)?
Because they're trained and graded in a way that rewards confident guessing over admitting uncertainty. A 2025 OpenAI and Georgia Tech paper frames hallucination as a natural statistical byproduct of this setup: generating correct text is harder than recognizing it, and most benchmarks penalize a model for saying "I don't know." The practical fix is a system that lets the model abstain and routes those cases to retrieval, a tool, or a human.
Q5.Will a bigger or newer model fix the reasoning problem?
Scaling has made models far more capable, but the evidence suggests it hasn't closed the core gap. Perturbation studies still show accuracy dropping on trivially altered problems, and real-world agent benchmarks still show leading systems completing only around a third of consequential tasks on their own. Graepel's own view is that you don't reach trustworthy machine intelligence by "making System 1 bigger." Architecture around the model is doing the heavy lifting, not model size alone.
Q6.How does Cloud Radix keep an AI Employee from giving confidently wrong answers?
We ground every answer in your current data and cite it, route real actions through governed tools instead of free text, run consequential outputs through verification and policy checks via our secure AI gateway, and escalate to a human when confidence is low. We also measure error and escalation rates on live traffic so problems surface as data, not as a surprise in front of a customer.
Sources & Further Reading
- MIT Technology Review: technologyreview.com/2026/10/02/1145639/dont-be-fooled-llms-dont-reason — Don't be fooled: LLMs don't reason (Thore Graepel).
- Apple (arXiv): arxiv.org/abs/2410.05229 — GSM-Symbolic: Understanding the Limitations of Mathematical Reasoning in Large Language Models.
- OpenAI & Georgia Tech (arXiv): arxiv.org/abs/2509.04664 — Why Language Models Hallucinate.
- Berkeley Artificial Intelligence Research (BAIR): bair.berkeley.edu/blog/2024/02/18/compound-ai-systems — The Shift from Models to Compound AI Systems.
- Anthropic: anthropic.com/research/reasoning-models-dont-say-think — Reasoning models don't always say what they think.
- Carnegie Mellon University et al. (arXiv): arxiv.org/abs/2412.14161 — TheAgentCompany: Benchmarking LLM Agents on Consequential Real World Tasks.
Want an AI Employee Built Around the Limitation?
We'll show you exactly how a grounded, governed, escalation-aware AI Employee would handle a real workflow in your Fort Wayne or Northeast Indiana business — and tell you honestly where a human still needs to hold the pen.
Schedule a Free ConsultationNo contracts. No pressure. Just an honest conversation about what would actually help.