Here's a fact that should reframe how you think about spending money on AI in 2026: the model your competitor uses is almost certainly the same one you can use. Same frontier capability, same API, same monthly bill. The intelligence has become a commodity you rent by the token. So if the brains are interchangeable, what actually separates the business that wins with AI from the one that just pays for it? The short answer is your proprietary data.
The answer is the thing nobody else can buy: the data only your business has. Your manufacturing run histories. Fifteen years of client files. Every quote you won and every one you lost. The service records that quietly encode what your best technician learned over a career. That is the raw material a rented model turns into an edge — and on September 28, 2026, Microsoft shipped a stack of tooling built specifically to make it usable. In its announcement, Microsoft argued the difference will come from how effectively organizations combine commoditized models with the data, expertise, and business context that make them unique.
We've made the strategic version of this argument before — that the model isn't your moat. This post is about the harder, less glamorous half of the story: owning the data isn't the advantage. Making it safely usable is. Most businesses in Northeast Indiana are sitting on decades of proprietary data their AI cannot touch, because it's ungoverned, unstructured, or trapped in silos. Here's what changed, and what it means for the work you actually have to do.
Key Takeaways
- Models are commoditized; your data is not. The durable AI advantage is proprietary business data and context — the one input a competitor cannot rent or replicate.
- Owning data isn't enough — it has to be usable. Most enterprise data is “dark”: stored but never activated, because it's ungoverned, unstructured, or siloed.
- Microsoft just shipped the plumbing. Fabric IQ (generally available) grounds Copilot answers in governed Power BI semantic models; Agentic Data Engineering, a cross-database Hub, and SQL Server on Azure Local round out the stack.
- A semantic layer is the unglamorous prerequisite. AI reasons over business meaning, not raw tables — and that meaning has to be defined, governed, and maintained before agents can use it safely.
- Human-in-control is the design, not an afterthought. The new autonomous data-prep agents plan and execute within boundaries a person sets.
- Independence matters for mid-market. Piping your governed data into AI shouldn't lock you to one model vendor — keep the data layer yours.
What did Microsoft actually announce — and why does it matter to a mid-market business?
Strip away the conference branding and Microsoft shipped one thing: infrastructure to take the data a business already owns and make it safely legible to AI. Five pieces matter, and they ship at different maturity levels — which is exactly what you need to know before you plan anything around them. Microsoft's Azure data team laid out the full lineup at FabCon and SQLCon 2026.
| Capability | What It Does | Status |
|---|---|---|
| Fabric IQ | Grounds Copilot Chat and Cowork answers in governed Power BI semantic models, metrics, and business definitions — so AI reasons over your numbers, not a generic guess | Generally available |
| IQ Sharing | Securely shares data and business context across organizational boundaries while keeping governance intact | Preview |
| Agentic Data Engineering | An autonomous agent that plans and executes long-running data prep — migrations, ETL, lakehouse modernization — inside guardrails an engineer sets | Preview |
| Database Hub in Fabric | A single control plane to monitor, govern, and assess risk across SQL Server, Azure SQL, PostgreSQL, Cosmos DB, and Fabric databases | Preview |
| SQL Server on Azure Local | Runs SQL Server close to your applications for low-latency access while you keep control over where data physically resides, including disconnected environments | Generally available |
The headline for a Fort Wayne operator isn't any single feature — it's the pattern. Every piece is about activation and governance, not raw model power. Fabric IQ is the clearest example. Instead of asking a chatbot a question and hoping it guesses right, Fabric IQ grounds the answer in the semantic models your team already trusts. As Microsoft's Copilot team put it, it pulls “trusted context from your data, including the 20+ million semantic models in Power BI” directly into Copilot — and, Microsoft says, it does so without additional AI token costs. The point of all of it is a meeting Microsoft's Jessica Hawk describes as the goal: instead of “spending the meeting uncovering and debating whose number was right, the team was able to get straight to what the numbers mean.”
That is a governance win disguised as a productivity feature. And it's the whole ballgame for mid-market.
If everyone has the same models, why is your data the advantage?
Because a frontier model, out of the box, knows everything about the world in general and nothing about your business in particular. It has never seen your pricing logic, your churn patterns, or the reason your Tuesday production line runs slower than your Thursday one. Those answers live in your data — and only your data.
Bain & Company frames this as the inversion at the center of AI strategy: as frontier models commoditize, proprietary data becomes the durable differentiator — a moat competitors cannot simply purchase, because accumulated customer, operational, and outcome data can't be synthesized by an outsider. Bain also makes a subtler point that matters more than the moat itself: the real value isn't just the historical archive, it's the live signal continuously replenished by what's happening in the business right now. Last year's data tells you what worked; today's tells you what's working.
We're not going to re-argue the strategy here — we've done that. What's worth sitting with is the uncomfortable corollary. If proprietary data is the advantage, then most businesses are leaving their single biggest AI asset locked in a drawer. Owning it and using it are completely different things, and the gap between them is where almost every mid-market AI project actually stalls.
Why can't AI use the data you already have?
Because most of it is what analysts call dark data — information a business collects and stores but never actually uses. Gartner's definition, cited by data-management firm Komprise, is blunt: dark data is the “information assets organizations collect, process and store during regular business activities but generally fail to use for other purposes.” By most estimates the majority of enterprise data falls into this bucket, and the overwhelming share of it is unstructured — emails, PDFs, scanned records, notes, images — the exact formats an AI can't reason over without help.
For a Northeast Indiana business, dark data usually takes three concrete forms:
- Ungoverned. Nobody can say who's allowed to see a given record, so it's too risky to feed an AI that might surface it to the wrong person. Without access controls, “let the AI read everything” is a data-breach waiting to happen.
- Unstructured. The knowledge exists — in a decade of service tickets, quote emails, and handwritten job notes — but not in any form a model can query. It's readable by a human, invisible to a machine.
- Siloed. The pieces that would matter together live apart: CRM here, accounting there, production logs on a shop-floor PC. No single system sees the whole picture, so neither can the AI.
There's a cruel irony hiding in the agentic era, too. The rush to give every AI agent its own data connection can quietly recreate the exact fragmentation you spent a decade eliminating — we wrote about AI agents quietly rebuilding the data silos you thought you'd torn down. Activation without governance doesn't fix the problem; it multiplies it.
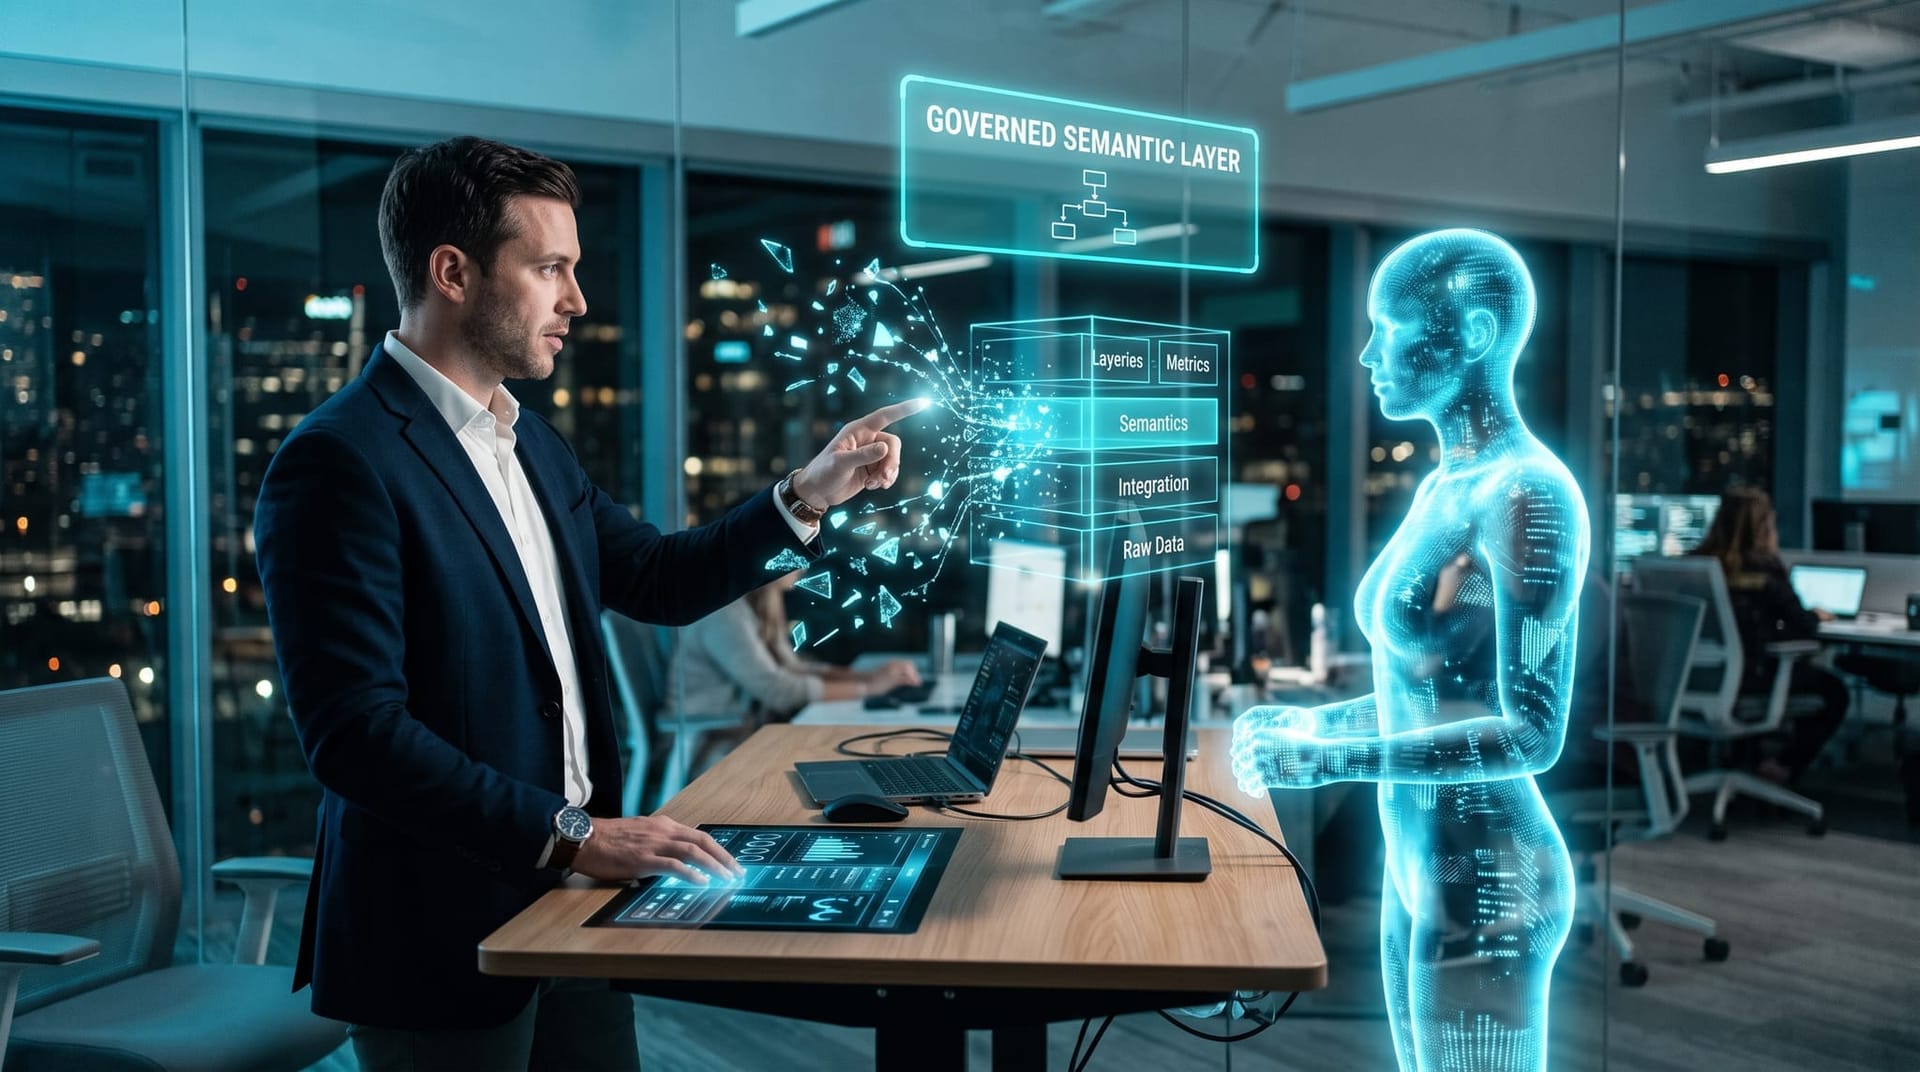
How do you actually make proprietary data usable for AI?
You build a layer between your raw data and the model — a place where business meaning is defined, governed, and kept current. This is the unglamorous work, and there's no shortcut around it. Bain calls it building a semantic layer: a shared business vocabulary that lets AI reason about what your data means, not just what it technically contains. “Revenue,” “active customer,” and “on-time delivery” have to mean one specific, governed thing before an agent can be trusted to answer a question about them.
This is precisely what Fabric IQ operationalizes. According to Microsoft's documentation, it combines unified data in OneLake, trusted metrics from Power BI semantic models, and operational context from ontologies into a shared understanding that both people and agents draw from. The AI stops guessing which table to use because the governed model already encodes the right answer. That's the difference between an AI that confidently invents a number and one that returns the number your finance team would sign off on.
The practical sequence for a mid-market team looks like this:
- Inventory and classify. Know what data you hold and who should be able to see it. Governance comes before activation, not after.
- Consolidate the silos. Get the operational data into one governed plane — the whole point of a central control layer like the new Database Hub is visibility across a scattered estate.
- Define the semantic layer. Agree, once, on what your core business terms mean, and encode that as governed models an AI can query.
- Activate with humans in control. Only then point AI at it — and keep a person in the loop.
That last point is worth underlining because Microsoft designed for it. Its new Agentic Data Engineering agent takes on genuinely tedious work — migrations, complex ETL, data prep — but the engineer defines the desired outcome and the guardrails, and the agent plans and executes inside them. Autonomous doesn't mean unsupervised. If you want a structured way to gauge where you stand before any of this, we published a data-readiness checklist built for exactly this assessment.
What about data that can't leave the building?
Some of your most valuable proprietary data is also your most sensitive — client files under confidentiality obligations, health records, financial details, proprietary process data you'd never want in a shared cloud. For a long time the honest trade-off was: you could keep that data private, or you could use AI on it, but not both cleanly.
That trade-off is softening. SQL Server on Azure Local, now generally available, lets a business run the database close to its own applications and operations while keeping control over where the data physically resides — and its disconnected-operations option is in preview for environments where cloud connectivity is restricted or intentionally cut off. For a manufacturer with data it won't send off-premises, or a professional-services firm bound by confidentiality, that matters: the data stays put, and the AI comes to it.
This is the same principle behind our guidance to keep confidential client files off the cloud while still getting AI value from them. The lesson holds regardless of vendor: sensitivity is a reason to architect carefully, not a reason to sit out. The data that's hardest to move is often the data that's most uniquely yours — which makes it exactly the data worth the extra engineering.
Which Northeast Indiana businesses are sitting on the richest untapped data?
Almost every established operation in Fort Wayne, Auburn, and across DeKalb and Allen Counties is a data-rich business that doesn't think of itself that way. The region's economic base is precisely the kind that accumulates deep proprietary records over decades.
Manufacturers hold years of run histories, machine telemetry, quality records, and maintenance logs — the highest-value dark data in the region, because it encodes hard-won operational knowledge no competitor can replicate. Professional-services firms — legal, accounting, engineering, consulting — sit on client files and matter histories that define their expertise. Financial-services institutions — community banks and credit unions — hold rich customer and transaction data under strict governance obligations, which is why we built the Fort Wayne financial-services data-readiness audit specifically for that sector. Healthcare and home-services operations quietly generate service records, scheduling patterns, and outcome data that could sharpen everything from staffing to pricing.
For every one of these, the sequence is the same: governance and readiness first, activation second. And there's a strategic caveat particular to mid-market operators who can't absorb the cost of a bad bet — keep your data layer independent of any single model provider. The models will keep changing and competing; your governed data should outlast all of them. Own the layer that's actually yours, and you can swap the commodity on top whenever a better or cheaper one ships.
Put your own data to work
At Cloud Radix, we deploy AI Employees for Fort Wayne and Northeast Indiana businesses — and the honest first step is almost never “add more AI.” It's making the data you already own governed, consolidated, and usable, so the AI you deploy on top of it produces answers you'd actually stake a decision on. That's the unglamorous groundwork that turns a rented model into a real edge.
If your business is sitting on decades of records you suspect are valuable but can't quite put to work, that's the conversation worth having. Get in touch and we'll help you map what you have, what it would take to make it usable, and where an AI Employee grounded in your data would pay off first.
Frequently Asked Questions
Q1.What does "proprietary data is the AI advantage" actually mean?
It means that because frontier AI models are broadly available to everyone at similar cost, the model itself no longer differentiates your business. What differentiates you is the data only you have — your records, history, and operational context. A model grounded in your proprietary data produces answers a competitor's identical model can't, which is why data, not the model, is the durable edge.
Q2.What is Fabric IQ and why does it matter for a small business?
Fabric IQ is Microsoft tooling, now generally available, that grounds Copilot's answers in your governed Power BI semantic models and business definitions rather than generic guesses. For a small or mid-market business it matters because it lets AI reason over your trusted numbers while keeping access controls intact — reducing the risk of an AI confidently inventing a figure or exposing data to the wrong person.
Q3.Why can't AI just use the data we already have?
Most business data is "dark" — stored but unusable by AI because it's ungoverned (no clear access rules), unstructured (emails, PDFs, notes a model can't query), or siloed across disconnected systems. Before AI can use it safely, that data has to be inventoried, governed, consolidated, and given a semantic layer that defines what the business terms actually mean.
Q4.What is a semantic layer and do we really need one?
A semantic layer is a governed, shared definition of what your core business terms mean — so "revenue" or "active customer" resolves to one specific, agreed value. You need it because AI reasons over meaning, not raw tables; without it, agents guess at which data to use and produce inconsistent or wrong answers. It's the unglamorous prerequisite for trustworthy AI activation.
Q5.Can a Northeast Indiana business use AI on sensitive data without sending it to the cloud?
Increasingly, yes. Options like SQL Server on Azure Local let you run databases close to your own operations and keep control over where data physically resides, including disconnected environments. For the confidentiality-bound firms common across Fort Wayne and Northeast Indiana — legal, healthcare, community banks and credit unions — that means you can apply AI to sensitive proprietary data while keeping that data on infrastructure you control.
Q6.How do we keep AI activation from creating new data silos?
By centralizing governance rather than giving each AI agent its own ad-hoc data connection. A shared, governed context layer and a single control plane across your databases prevent the fragmentation that happens when every agent reaches into data on its own terms. Governance has to lead activation, or you rebuild the silos you spent years eliminating.
Q7.Should we commit to one AI vendor's data stack?
Be deliberate about it. Grounding AI in your governed data is valuable, but your data layer is the asset that should outlast any single model or vendor. Keep that layer independent enough that you can switch the commodity model on top as better or cheaper options appear — especially important for mid-market operators who can't afford lock-in.
Sources & Further Reading
- The Official Microsoft Blog: blogs.microsoft.com/blog/2026/09/28/new-microsoft-data-innovations-unlock-what-only-your-business-knows — New Microsoft data innovations unlock what only your business knows.
- Microsoft Azure Blog: azure.microsoft.com/en-us/blog/fabcon-and-sqlcon-2026-in-barcelona — Building the data foundation for Microsoft Copilot and agents (FabCon and SQLCon 2026).
- Microsoft Learn: learn.microsoft.com/en-us/fabric/iq/connectors/cowork-overview — Fabric IQ in Microsoft 365 Copilot Cowork.
- The Official Microsoft Blog: blogs.microsoft.com/blog/2026/09/25/introducing-the-new-copilot-with-home-code-and-autopilot — Introducing the new Copilot with Home, Code and Autopilot.
- Bain & Company: bain.com/insights/solutions/turn-artificial-intelligence-into-proprietary-intelligence/decision-3-proprietary-data — Turn AI into proprietary intelligence: Proprietary data.
- Komprise: komprise.com/glossary_terms/dark-data — What Is Dark Data? Risks, Costs and Hidden Value for Enterprise AI.
Turn Your Data Into a Real AI Edge
We'll map the proprietary data you already own, show you what it would take to make it governed and usable, and pinpoint where an AI Employee grounded in your data pays off first — for your Fort Wayne or Northeast Indiana business.
Schedule a Free ConsultationNo contracts. No pressure. Just an honest conversation about your data.